Protein Metabolism
chapter
27
1. Messenger RNA Translation Predict the amino acid sequences of peptides formed by ribosomes in
response to the following mRNA sequences, assuming that the reading frame begins with the first
three bases in each sequence.
(a) GGUCAGUCGCUCCUGAUU
(b) UUGGAUGCGCCAUAAUUUGCU
(c) CAUGAUGCCUGUUGCUAC
(d) AUGGACGAA
2. How Many Different mRNA Sequences Can Specify One Amino Acid Sequence? Write all the
possible mRNA sequences that can code for the simple tripeptide segment Leu–Met–Tyr. Your answer
will give you some idea about the number of possible mRNAs that can code for one polypeptide.
3. Can the Base Sequence of an mRNA Be Predicted from the Amino Acid Sequence of Its
Polypeptide Product? A given sequence of bases in an mRNA will code for one and only one se-
quence of amino acids in a polypeptide, if the reading frame is specified. From a given sequence of
amino acid residues in a protein such as cytochrome c, can we predict the base sequence of the
unique mRNA that coded it? Give reasons for your answer.
c27ProteinMetabolism.qxd 12/12/12 6:49 PM Page S-301
S-302 Chapter 27 Protein Metabolism
4. Coding of a Polypeptide by Duplex DNA The template strand of a segment of double-helical DNA
contains the sequence
(5⬘)CTTAACACCCCTGACTTCGCGCCGTCG(3⬘)
(a) What is the base sequence of the mRNA that can be transcribed from this strand?
(b) What amino acid sequence could be coded by the mRNA in (a), starting from the 5⬘end?
(c) If the complementary (nontemplate) strand of this DNA were transcribed and translated, would
the resulting amino acid sequence be the same as in (b)? Explain the biological significance of
your answer.
Answer The template strand serves as the template for RNA synthesis; the nontemplate
strand is identical in sequence to the RNA transcribed from the gene, with U in place of T.
5. Methionine Has Only One Codon Methionine is one of two amino acids with only one codon. How
does the single codon for methionine specify the initiating residue and interior Met residues of
polypeptides synthesized by E. coli?
6. Synthetic mRNAs The genetic code was elucidated with polyribonucleotides synthesized either
enzymatically or chemically in the laboratory. Given what we now know about the genetic code, how
would you make a polyribonucleotide that could serve as an mRNA coding predominantly for many
Phe residues and a small number of Leu and Ser residues? What other amino acid(s) would be coded
for by this polyribonucleotide, but in smaller amounts?
7. Energy Cost of Protein Biosynthesis Determine the minimum energy cost, in terms of ATP equiva-
lents expended, required for the biosynthesis of the b-globin chain of hemoglobin (146 residues),
starting from a pool including all necessary amino acids, ATP, and GTP. Compare your answer with the
direct energy cost of the biosynthesis of a linear glycogen chain of 146 glucose residues in (a1n4) link-
age, starting from a pool including glucose, UTP, and ATP (Chapter 15). From your data, what is the
extra energy cost of making a protein, in which all the residues are ordered in a specific sequence,
compared with the cost of making a polysaccharide containing the same number of residues but
lacking the informational content of the protein?
In addition to the direct energy cost for the synthesis of a protein, there are indirect energy
costs—those required for the cell to make the necessary enzymes for protein synthesis. Compare the
magnitude of the indirect costs to a eukaryotic cell of the biosynthesis of linear (a1n4) glycogen
chains and the biosynthesis of polypeptides, in terms of the enzymatic machinery involved.
8. Predicting Anticodons from Codons Most amino acids have more than one codon and attach to
more than one tRNA, each with a different anticodon. Write all possible anticodons for the four codons
of glycine: (5⬘)GGU, GGC, GGA, and GGG.
(a) From your answer, which of the positions in the anticodons are primary determinants of their
codon specificity in the case of glycine?
(b) Which of these anticodon-codon pairings has/have a wobbly base pair?
(c) In which of the anticodon-codon pairings do all three positions exhibit strong Watson-Crick
hydrogen bonding?
S-304 Chapter 27 Protein Metabolism
Answer All the anticodons for the four Gly codons have the sequence (5⬘)XCC. The first
9. Effect of Single-Base Changes on Amino Acid Sequence Much important confirmatory evidence
on the genetic code has come from assessing changes in the amino acid sequence of mutant proteins
after a single base has been changed in the gene that encodes the protein. Which of the following
amino acid replacements would be consistent with the genetic code if the replacements were caused
by a single base change? Which cannot be the result of a single-base mutation? Why?
(a) PhenLeu (e) IlenLeu
(b) LysnAla (f) HisnGlu
(c) AlanThr (g) PronSer
(d) PhenLys
10. Resistance of the Genetic Code to Mutation The following RNA sequence represents the begin-
ning of an open reading frame. What changes (if any) can occur at each position without generating a
change in the encoded amino acid residue?
(5⬘)AUGAUAUUGCUAUCUUGGACU
11. Basis of the Sickle-Cell Mutation Sickle-cell hemoglobin has a Val residue at position 6 of the
b-globin chain, instead of the Glu residue found in normal hemoglobin A. Can you predict what change
took place in the DNA codon for glutamate to account for replacement of the Glu residue by Val?
12. Proofreading by Aminoacyl-tRNA Synthetases The isoleucyl-tRNA synthetase has a proofreading
function that ensures the fidelity of the aminoacylation reaction, but the histidyl-tRNA synthetase
lacks such a proofreading function. Explain.
S-306 Chapter 27 Protein Metabolism
13. Importance of the “Second Genetic Code” Some aminoacyl-tRNA synthetases do not recognize
and bind the anticodon of their cognate tRNAs but instead use other structural features of the tRNAs
to impart binding specificity. The tRNAs for alanine apparently fall into this category.
(a) What features of tRNA
Ala
are recognized by Ala-tRNA synthetase?
(b) Describe the consequences of a CnG mutation in the third position of the anticodon of tRNA
Ala
.
(c) What other kinds of mutations might have similar effects?
(d) Mutations of these types are never found in natural populations of organisms. Why? (Hint: Con-
sider what might happen both to individual proteins and to the organism as a whole.)
Answer
14. The Role of Translation Factors A researcher isolates mutant variants of the bacterial translation
factors IF-2, EF-Tu, and EF-G. In each case, the mutation allows proper folding of the protein and the
binding of GTP but does not allow GTP hydrolysis. At what stage would translation be blocked by each
mutant protein?
15. Maintaining the Fidelity of Protein Synthesis The chemical mechanisms used to avoid errors in
protein synthesis are different from those used during DNA replication. DNA polymerases use a 3⬘n5⬘
exonuclease proofreading activity to remove mispaired nucleotides incorrectly inserted into a growing
DNA strand. There is no analogous proofreading function on ribosomes and, in fact, the identity of an
amino acid attached to an incoming tRNA and added to the growing polypeptide is never checked.
A proofreading step that hydrolyzed the previously formed peptide bond after an incorrect amino acid
had been inserted into a growing polypeptide (analogous to the proofreading step of DNA poly-
merases) would be impractical. Why? (Hint: Consider how the link between the growing polypeptide
and the mRNA is maintained during elongation; see Figs. 27–29 and 27–30.)
16. Predicting the Cellular Location of a Protein The gene for a eukaryotic polypeptide 300 amino
acid residues long is altered so that a signal sequence recognized by SRP occurs at the polypeptide’s
amino terminus and a nuclear localization signal (NLS) occurs internally, beginning at residue 150.
Where is the protein likely to be found in the cell?
17. Requirements for Protein Translocation across a Membrane The secreted bacterial protein
OmpA has a precursor, ProOmpA, which has the amino-terminal signal sequence required for
secretion. If purified ProOmpA is denatured with 8
M
urea and the urea is then removed (such as by
running the protein solution rapidly through a gel filtration column) the protein can be translocated
across isolated bacterial inner membranes in vitro. However, translocation becomes impossible if
ProOmpA is first allowed to incubate for a few hours in the absence of urea. Furthermore, the capacity
for translocation is maintained for an extended period if ProOmpA is first incubated in the presence of
another bacterial protein called trigger factor. Describe the probable function of this factor.
18. Protein-Coding Capacity of a Viral DNA The 5,386 bp genome of bacteriophage fX174 includes
genes for 10 proteins, designated A to K, with sizes given in the table below. How much DNA would be
required to encode these 10 proteins? How can you reconcile the size of the fX174 genome with its
protein-coding capacity?
Protein Number of amino
acid residues
A 455
B 120
C86
D 152
E91
F 427
G 175
H 328
J38
K56
S-308 Chapter 27 Protein Metabolism
Data Analysis Problem
19. Designing Proteins by Using Randomly Generated Genes Studies of the amino acid sequence
and corresponding three-dimensional structure of wild-type or mutant proteins have led to significant
insights into the principles that govern protein folding. An important test of this understanding would
be to design a protein based on these principles and see whether it folds as expected.
Kamtekar and colleagues (1993) used aspects of the genetic code to generate random protein
sequences with defined patterns of hydrophilic and hydrophobic residues. Their clever approach
combined knowledge about protein structure, amino acid properties, and the genetic code to explore
the factors that influence protein structure.
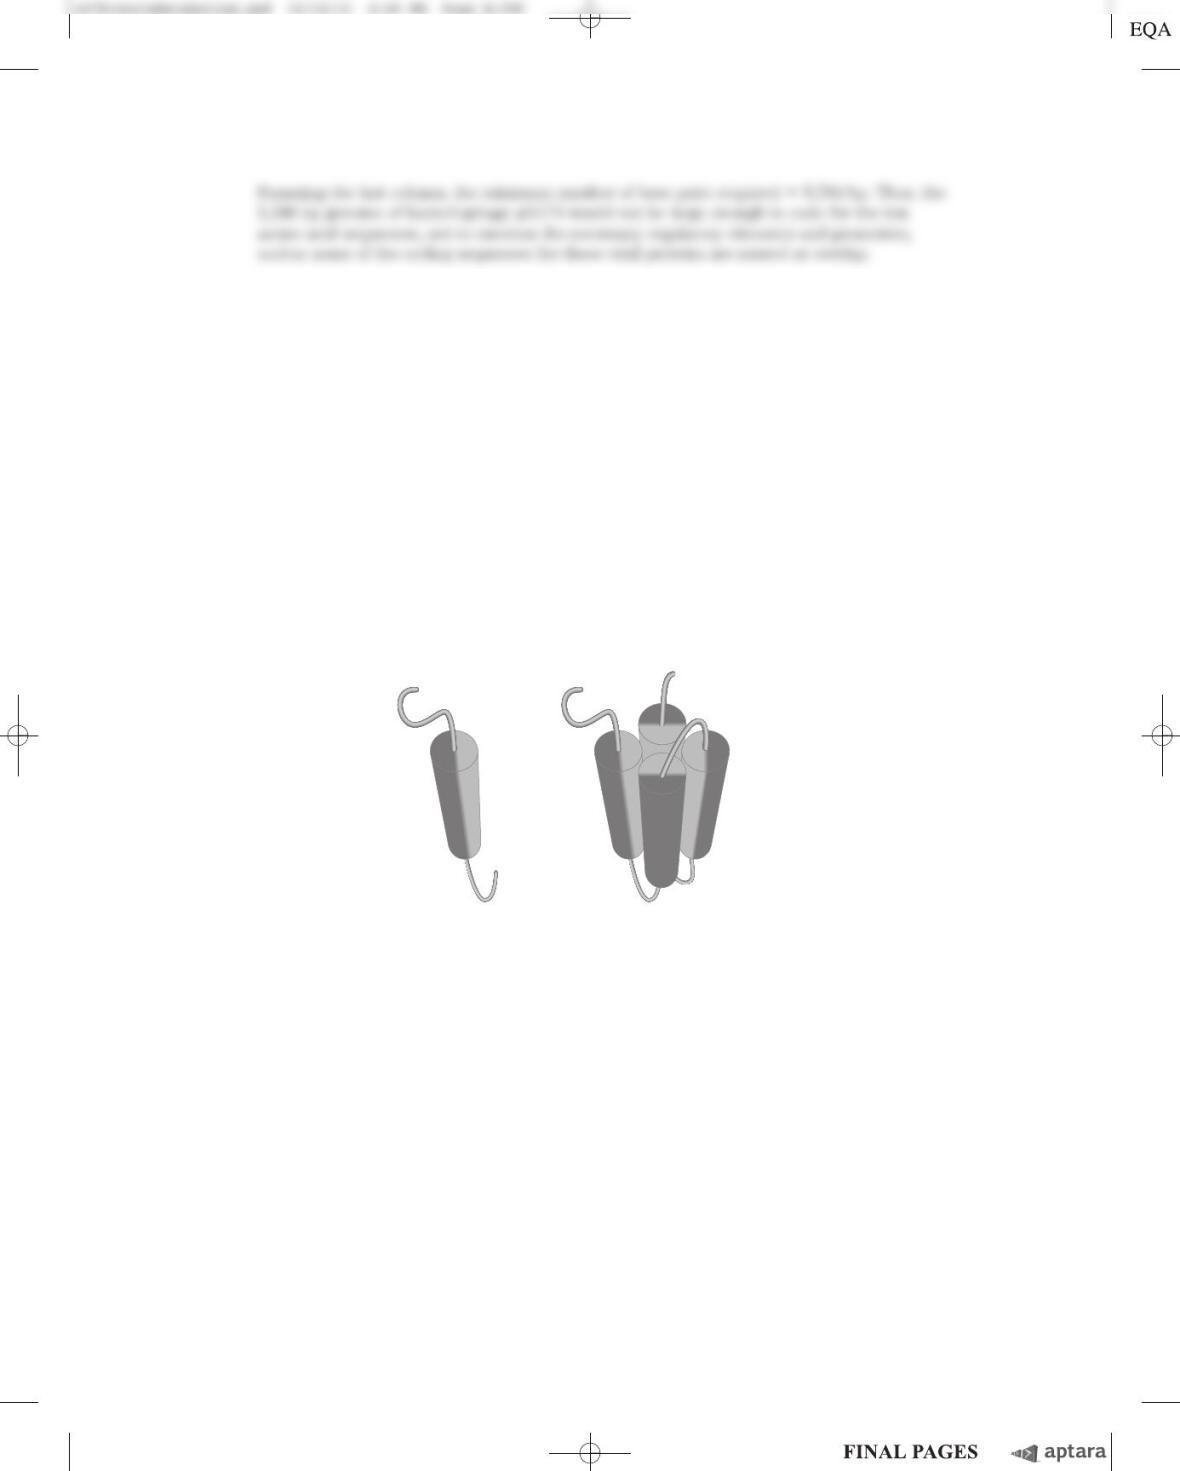
They set out to generate a set of proteins with the simple four-helix bundle structure shown below,
with ␣helices (shown as cylinders) connected by segments of random coil. Each ␣helix is amphipathic—
the R groups on one side of the helix are exclusively hydrophobic (light gray) and those on the other
side are exclusively hydrophilic (dark gray). A protein consisting of four of these helices separated by
short segments of random coil would be expected to fold so that the hydrophilic sides of the helices
face the solvent.
COO–
NH3
+COO–
NH3
+
A
n amphipathic a helix Four-helix bundle
(a) What forces or interactions hold the four ␣helices together in this bundled structure?
Figure 4–4a shows a segment of ␣helix consisting of 10 amino acid residues. With the gray cen-
tral rod as a divider, four of the R groups (purple spheres) extend from the left side of the helix and
six extend from the right.
(b) Number the R groups in Figure 4–4a, from top (amino terminus; 1) to bottom (carboxyl termi-
nus; 10). Which R groups extend from the left side and which from the right?
(c) Suppose you wanted to design this 10 amino acid segment to be an amphipathic helix, with the
left side hydrophilic and the right side hydrophobic. Give a sequence of 10 amino acids that
could potentially fold into such a structure. There are many possible correct answers here.
(d) Give one possible double-stranded DNA sequence that could encode the amino acid sequence
you chose for (c). (It is an internal portion of a protein, so you do not need to include start or
stop codons.)
Rather than designing proteins with specific sequences, Kamtekar and colleagues designed pro-
teins with partially random sequences, with hydrophilic and hydrophobic amino acid residues placed in
a controlled pattern. They did this by taking advantage of some interesting features of the genetic code
to construct a library of synthetic DNA molecules with partially random sequences arranged in a partic-
ular pattern.
To design a DNA sequence that would encode random hydrophobic amino acid sequences, the
researchers began with the degenerate codon NTN, where N can be A, G, C, or T. They filled each N
position by including an equimolar mixture of A, G, C, and T in the DNA synthesis reaction to gener-
ate a mixture of DNA molecules with different nucleotides at that position (see Fig. 8–35). Simi-
larly, to encode random polar amino acid sequences, they began with the degenerate codon NAN
and used an equimolar mixture of A, G, and C (but in this case, no T) to fill the N positions.
(e) Which amino acids can be encoded by the NTN triplet? Are all amino acids in this set hydropho-
bic? Does the set include all the hydrophobic amino acids?
(f) Which amino acids can be encoded by the NAN triplet? Are all of these polar? Does the set in-
clude all the polar amino acids?
(g) In creating the NAN codons, why was it necessary to leave T out of the reaction mixture?
Kamtekar and coworkers cloned this library of random DNA sequences into plasmids, selected 48
that produced the correct patterning of hydrophilic and hydrophobic amino acids, and expressed
these in E. coli. The next challenge was to determine whether the proteins folded as expected. It
would be very time-consuming to express each protein, crystallize it, and determine its complete
three-dimensional structure. Instead, the investigators used the E. coli protein-processing machinery
to screen out sequences that led to highly defective proteins. In this initial screening, they kept only
those clones that resulted in a band of protein with the expected molecular weight on SDS polyacry-
lamide gel electrophoresis (see Fig. 3–18).
(h) Why would a grossly misfolded protein fail to produce a band of the expected molecular weight
on electrophoresis?
Several proteins passed this initial test, and further exploration showed that they had the ex-
pected four-helix structure.
(i) Why didn’t all of the random-sequence proteins that passed the initial screening test pro-
duce four-helix structures?
Answer
Chapter 27 Protein Metabolism S-309
c27ProteinMetabolism.qxd 12/12/12 6:49 PM Page S-309
S-310 Chapter 27 Protein Metabolism