CHAPTER 4 A MARKOV CHAIN WITH REWARDS (MCR)
4.1
4.1 a)
State = 1
2
3
4
p(0) = 0.25
0.25
0.25
0.25
p(1) = p(0)P = 0.175
0.4
0.2
0.225
p(2) = p(1)P = 0.2
0.46
0.1625
0.1775
p(3) = p(2)P = 0.20825
0.47875
0.142
0.171
(3) 255.15pq
4.1 b)
S
[0.209651 0.480865 0.134775 0.174709]
4.1 c)
1
2
3
4
1
0.09
0.18
0.18
0.45
αP = 2
0.27
0.63
0
0
3
0.18
0.45
0.27
0
4
0.09
0.18
0.27
0.36
1
2
3
4
1
2.736363
3.95329
1.386338
1.92401
1.996806
5.58754
1.011652
3
1.905627
4.41916
2.335321
1.33989
4
1.750339
3.99176
1.464695
2.79321
37
4.2
4.2 a)
State 5 4 1 2 3
5, Sell to son 10000
4, Sell to daughter 0 1 0 0 0 0
1, Weekly income $10,000 0.05 0.10 0.40 0.25 0.20
I
PDQ
ªº
«
¬¼
»
º
ª
R
q
000,20$3
$15,000 2
daughter toSell 4
son toSell 5
incomeWeekly State
»
º
«
ª
»
º
«
ª
000,10$
1
1
1
q
4.2 b)
1
2
3
U = (I – Q)-1 =1
2.426778
1.199442
0.864714
2
0.920502
2.064156
0.55788
3
1.129707
1.018131
1.896792
5
4
1
0.431
0.569
F = UD = (I – Q)-1D = 2
0.439
0.561
3
0.494
0.506
4.2 c)
4.2 d) Given that the firm’s income in the first week is $15,000, the expected number of
38
absorption in state 4. This quantity is the sum of the entries in row 2 of the fundamental
1
ij
iC
410 0 0
0.1(1) 0.4(0.569) 0.25(0.561) 0.2(0.506)
10.569 0.569 0.569 0.569
3
ªº
«»
«»
41 2 3
4123
41 0 0 0
0
1 0.176 0.4 0.246 0.178
I
ªº
«»
ªº
¬¼
1
2
3
1
()UIQ
1
2.426205
1.180788
0.768765
2
0.933572
2.063473
0.502698
3
1.270024
1.128418
1.896603
4.2 e)
1
59553.7
UqT = 2
51324.97
3
64504.88
2
T
Suppose the following additional question is asked.
39
income that will be earned before the firm is sold to the daughter?
T
Uq
1
57349.2
2
50341.8
3
67558.6
Given that the firm’s income in the first week is $15,000, the expected total income that
will be earned before the firm is sold to the daughter =
2
()
T
Uq
50341.8.
4. 3
4.3a)
The components
i
q
of the cost vector are
60$57$)10/3(10$
0
q
2
20$10$)1(10$
3
q
3210
4.3b)
State 0 1 2 3 State
230
21
200
33
320
31000
4.3c) In matrix form the VDEs are
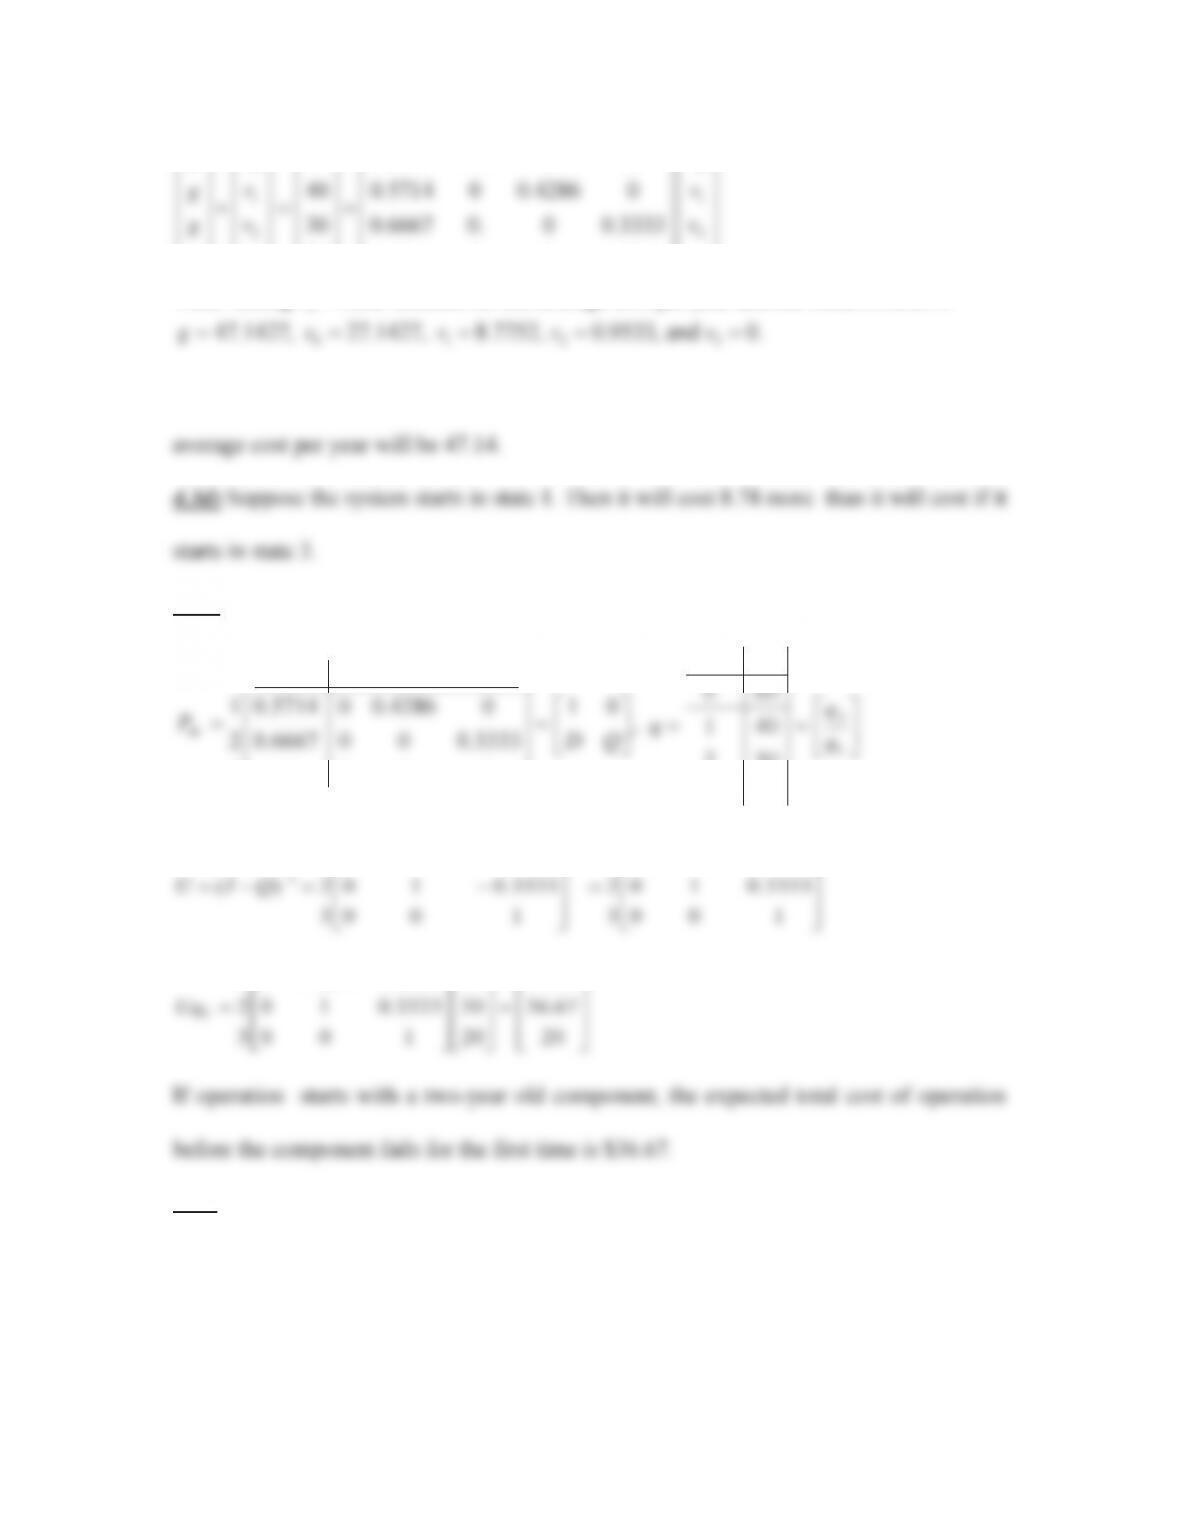
40
0 0
3 3
60 0.30 0.70 0 0
20 1 0 0 0
After setting 0,the solution for the average cost per year and
vv
g
vv
g
v
ªº ªº
ªº ª º ª º
«» «»
«» « » « »
¬¼ ¬ ¼ ¬ ¼
¬¼ ¬¼
the relative costs is
Thus, if this Markov chain with costs operates over an infinite planning horizon, the
4.3e) Make the target recurrent state 0 an absorbing state.
º
ª
»
»
º
«
«
ª
01
04286.005714.0
0001
1
0
º
ª
A
q
State
600
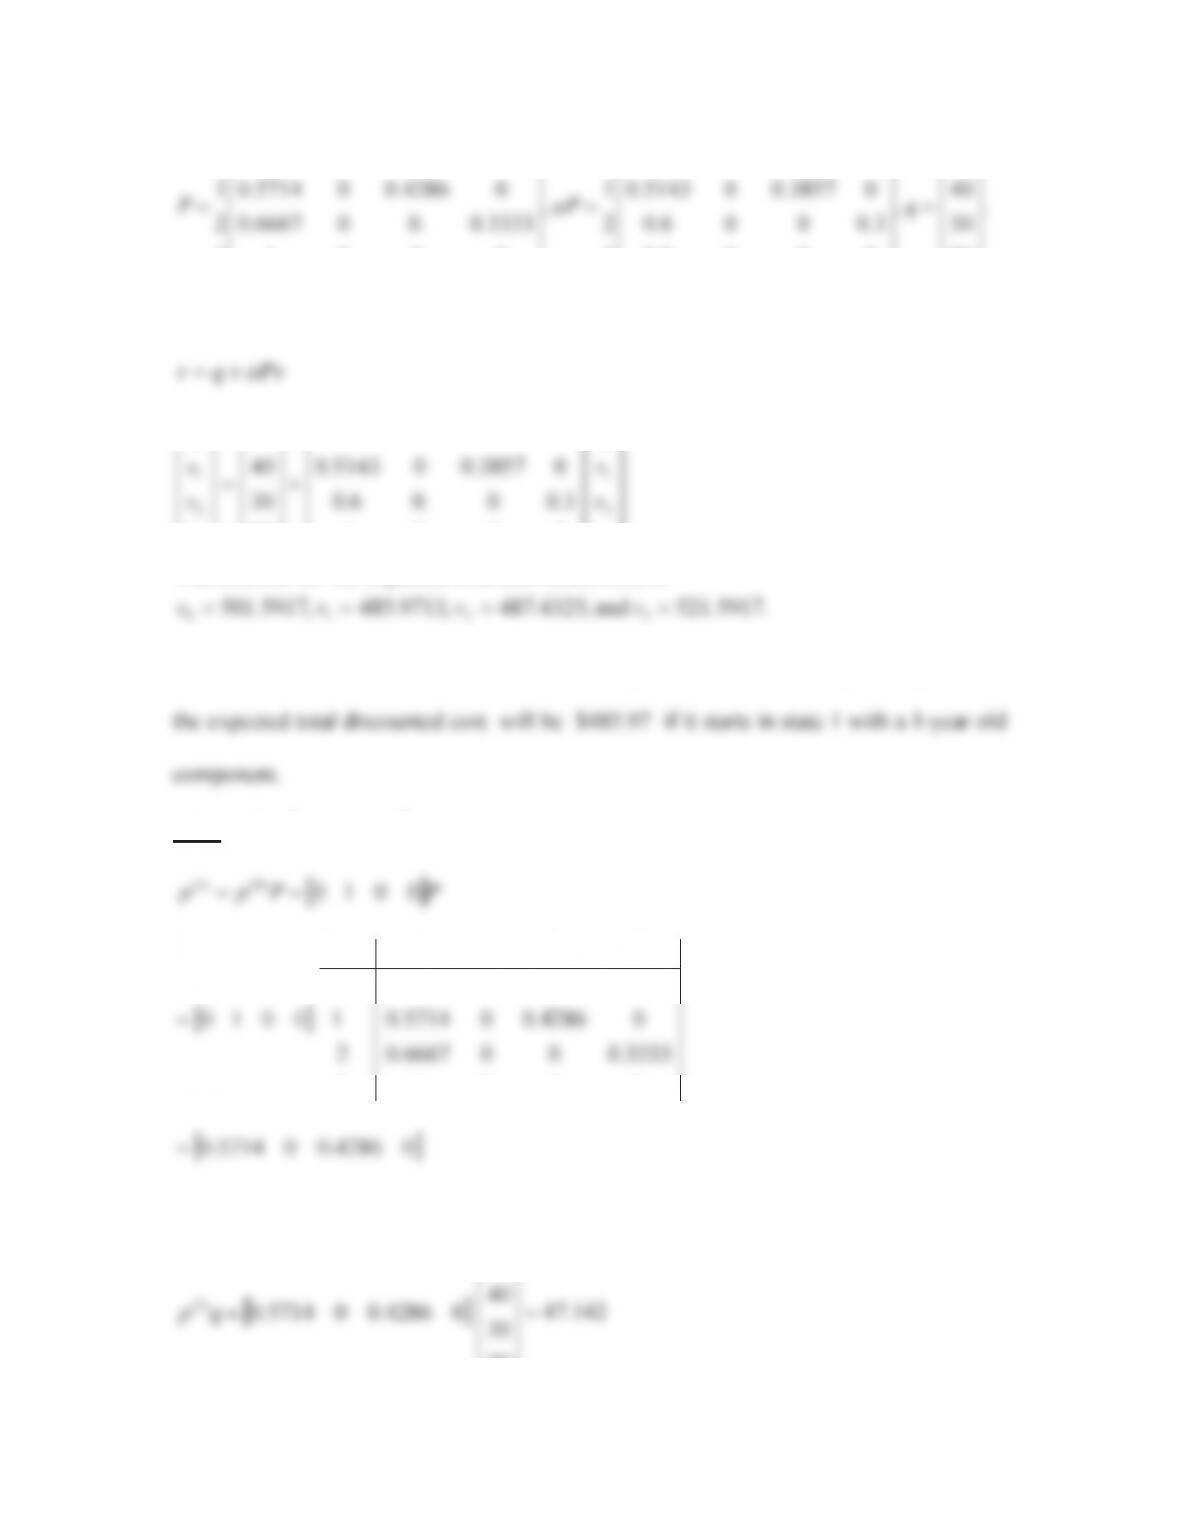
4.3f) With discounting, the model has the following transition probability matrix, P,
discount factor
9.0
D
, discounted matrix,
P
D
, and cost vector, q.
41
20
30
40
60
0009.0
3.0006.0
03857.005143.0
0063.027.0
3
2
1
0
0001
3333.0.006667.0
04286.005714.0
0070.030.0
3
2
1
0
»
»
»
»
¼
º
«
«
«
«
¬
ª
»
»
»
»
¼
º
«
«
«
«
¬
ª
»
»
»
»
¼
º
«
«
«
«
¬
ª
In matrix form the VDEs are
Thus, if this Markov chain with discounted costs operates over an infinite planning horizon,
4.3g)
>@
0010
)0(
p
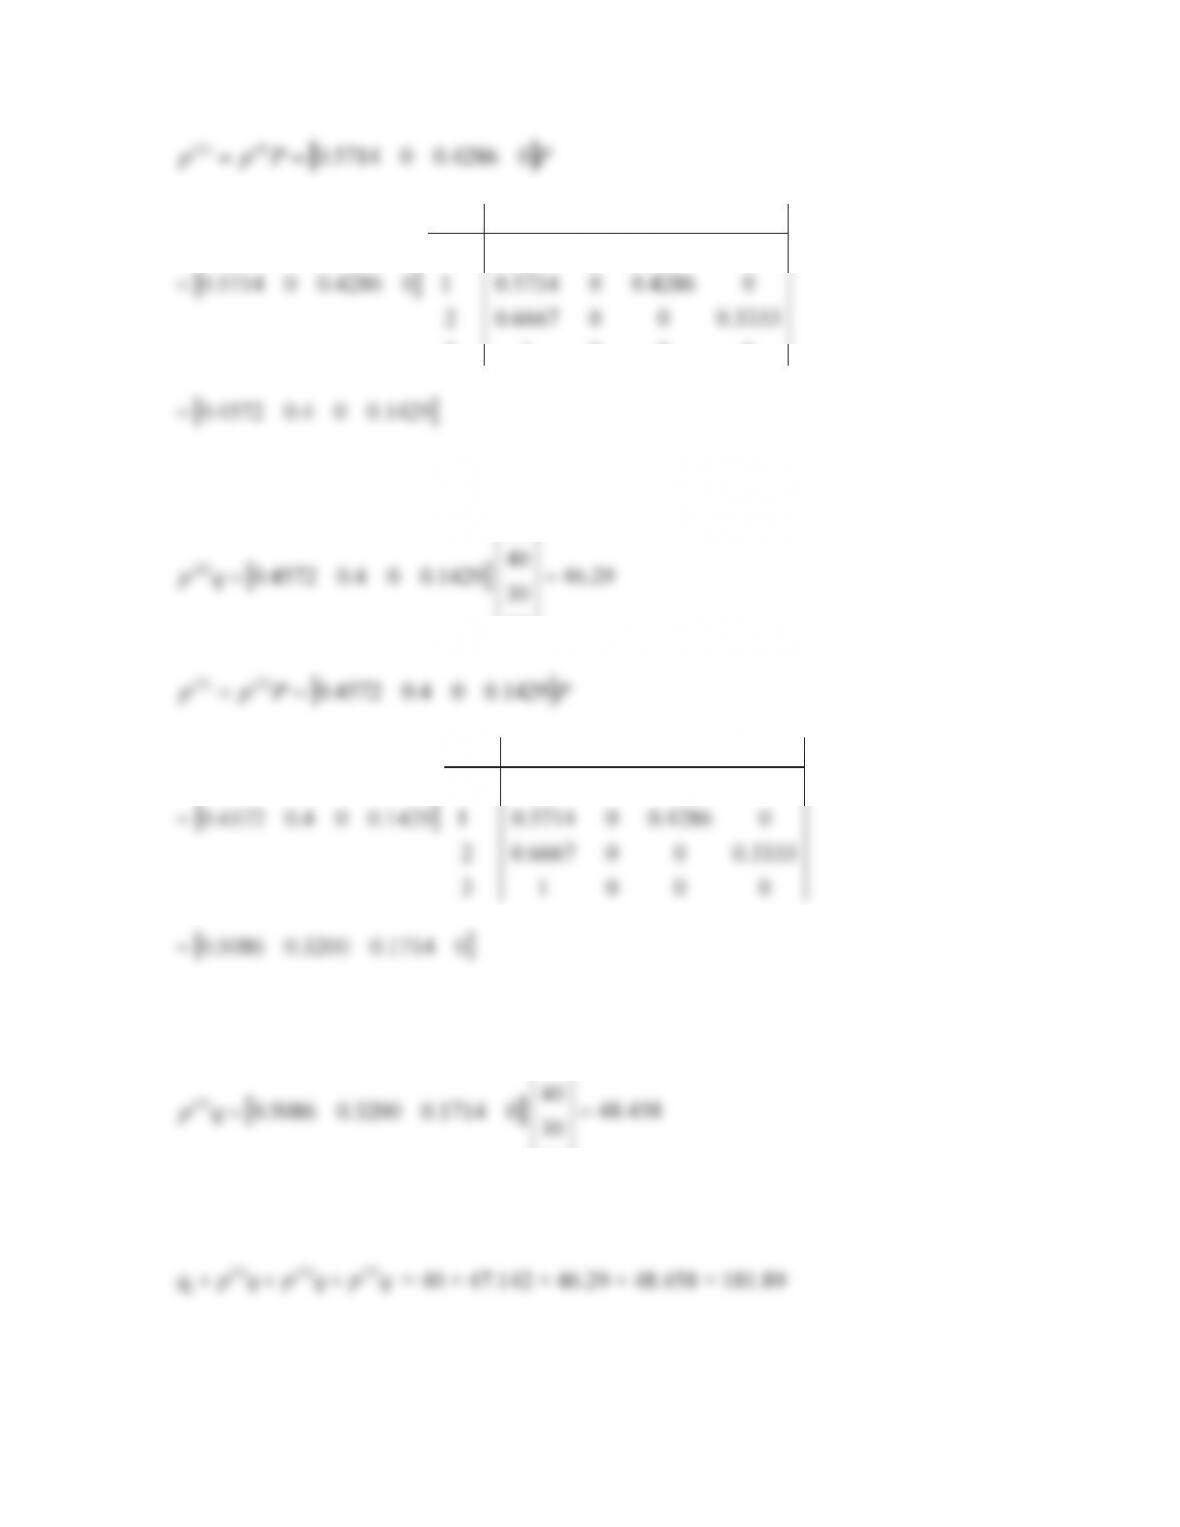
)0()1(
At the end of year 1, the expected cost of operation is
)1(
20
30
40
60
»
»
»
»
¼
º
«
«
«
«
¬
ª
42
)1()2(
At the end of year 2, the expected cost of operation is
)2(
40
60
»
»
º
«
«
ª
At the end of year 3, the expected cost of operation is
)3(
20
30
40
60
»
»
»
»
¼
º
«
«
«
«
¬
ª
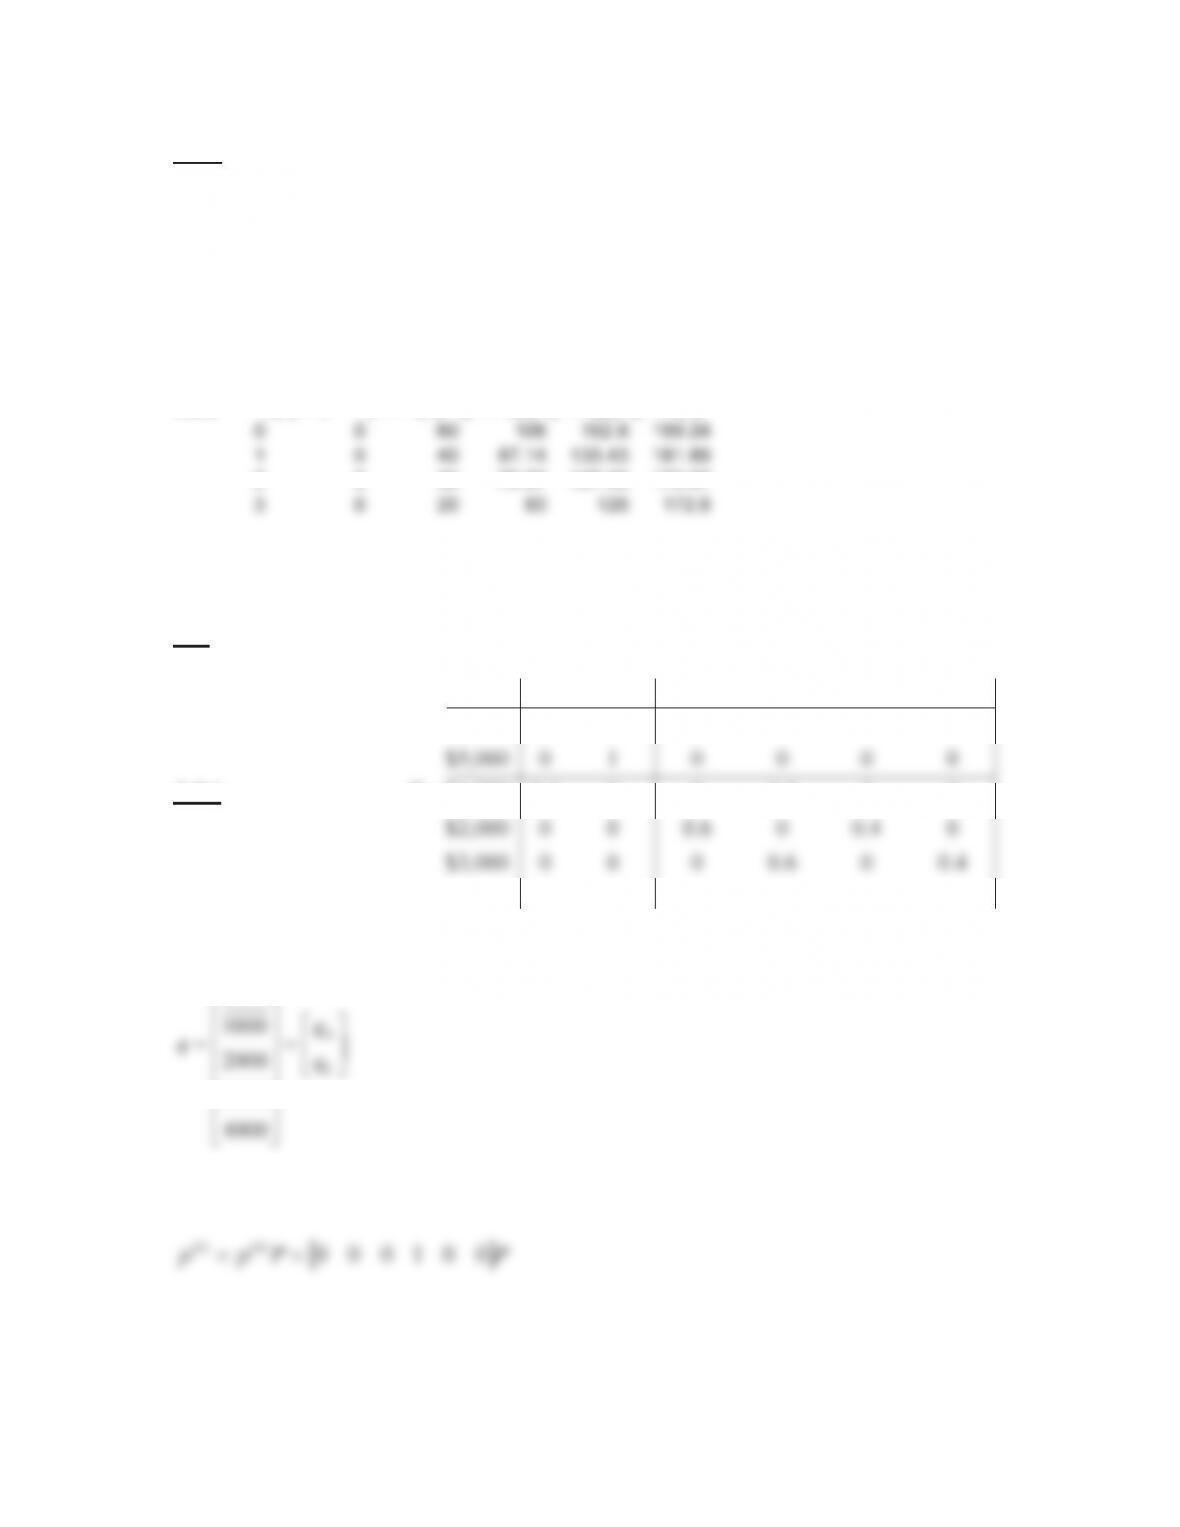
The expected total cost of operation after three years is
43
4.3h) Since value iteration assumes zero terminal costs at the end of a planning horizon, it
will be executed over four years to calculate the expected total cost after three years.
v(3) =
v(2) =
v(1) =
v(0) =
State
v(4) = 0
q +P v(4)
q+ P v(3)
q +Pv(2)
q+ Pv(1)
0
0
60
106
152.8
199.24
1
0
40
87.14
133.43
181.89
2
0
30
76.67
127.33
173.87
3
0
20
80
126
172.8
v1(0) = 181.89
4.4)
4.4a)
State $0 $5,000 $1,000 $2,000 $3,000 $4,000
$0100000
$1,000 0.6 0 0 0.4 0 0
$4,000 0 0.4 0 0 0.6 0
P
,
0
5000
3000
4000
ªº
«»
«»
«»
¬¼
>@
001000
)0(
p
)0()1(
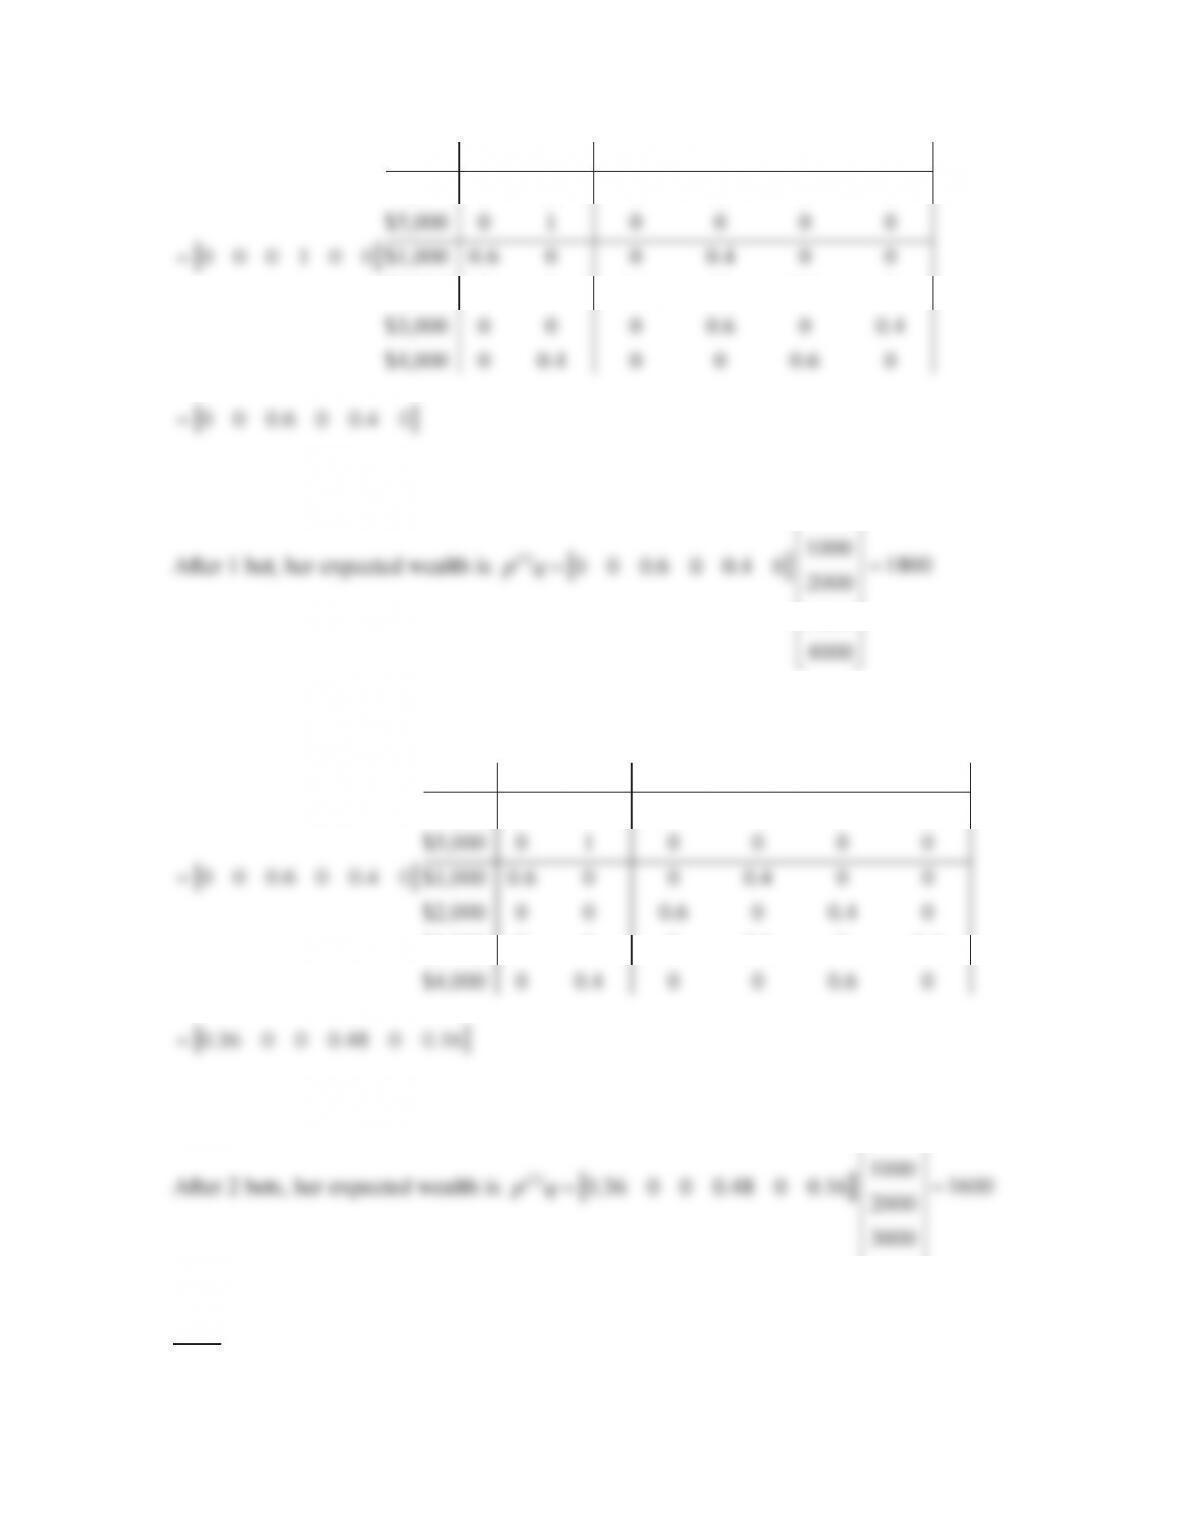
44
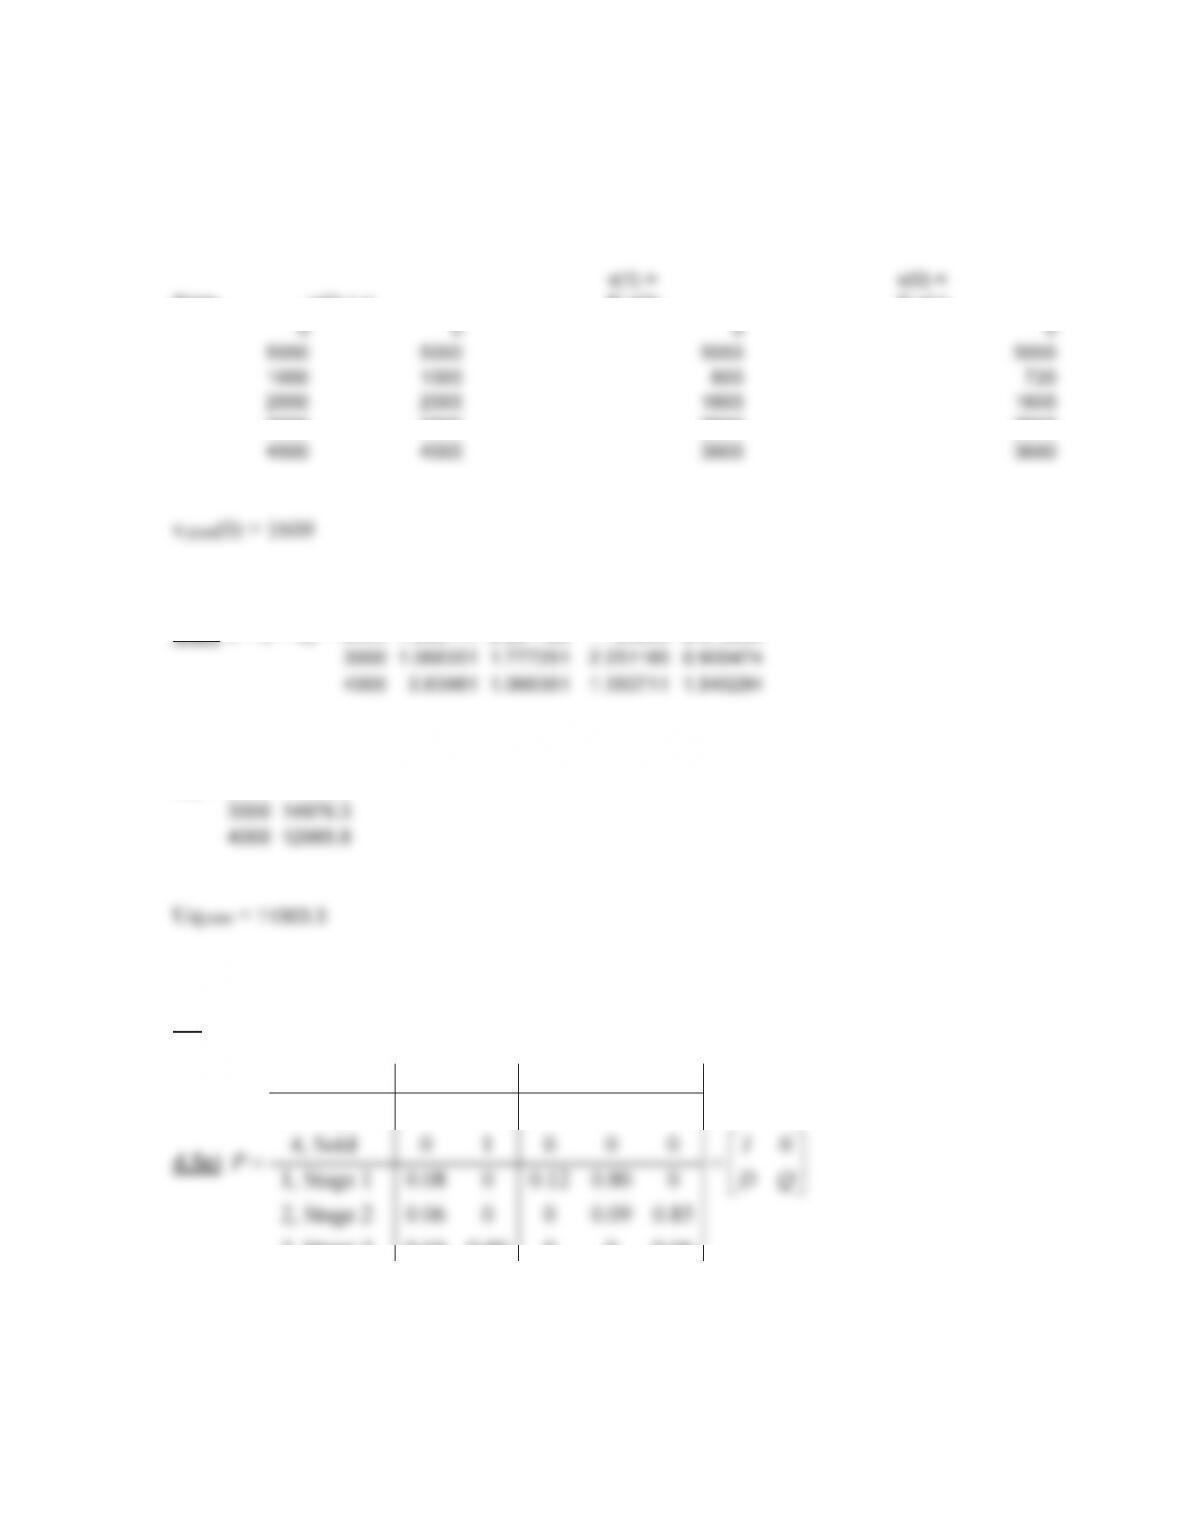
State $0 $5,000 $1,000 $2,000 $3,000 $4,000
$0100000
$2,000 0 0 0.6 0 0.4 0
>@
PPpp 04.006.000
)1()2(
State $0 $5,000 $1,000 $2,000 $3,000 $4,000
$0100000
$3,000 0 0 0 0.6 0 0.4
4000
3000
2000
»
»
»
»
¼
«
«
«
«
¬
4.4b) Value iteration is modified by setting v(2) = q, and making the reward vector a null vector.
45
When an absorbing state is entered, the expected total reward does not change because the
game has ended.
v(1) =
v(0) =
State
v(2) = q
P v(2)
P v(1)
0
0
0
0
5000
5000
5000
5000
1000
1000
800
720
2000
2000
1800
1600
3000
3000
2800
2600
4000
4000
3800
3680
1000
2000
3000
4000
1000
1.540284
0.900474
0.473934
0.189573
4.4c) U = (I – Q)
-1
=2000
1.350711
2.251185
1.184834
0.473934
3000
1.066351
1.777251
2.251185
0.900474
4000
0.63981
1.066351
1.350711
1.540284
1000
5521.33
UqT = 2000
11303.3
3000
14976.3
4000
12985.8
4.5
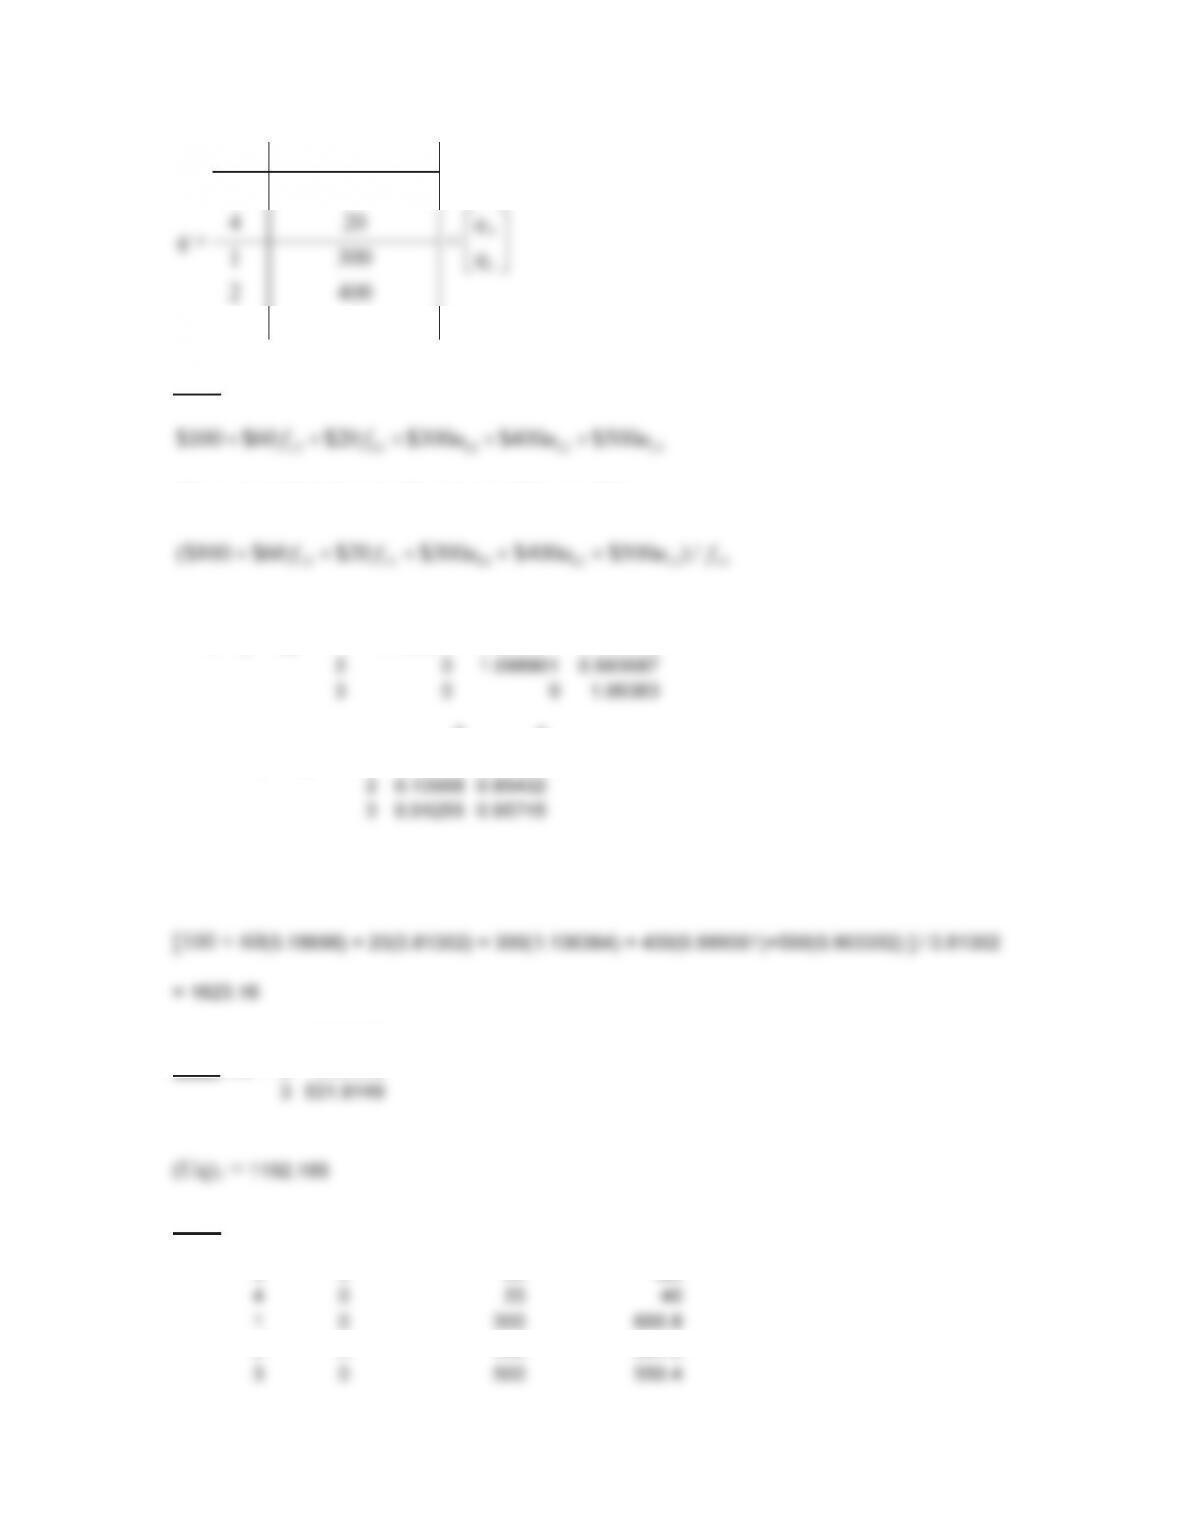
State 5 4 1 2 3
5, Scrapped 10000
3, Stage 3 0.04 0.90 0 0 0.06
46
State Cost (in dollars)
560
3500
4.5b) The expected cost per item started is
1312111415 500$400$300$20$60$100$uuuff
The expected total cost of an item sold is equal to
141312111415
/)500$400$300$20$60$100($ fuuuff
1
2
3
U = (I – Q)-1 = 1
1.136364
0.999001
0.903352
2
0
1.098901
0.993687
3
0
0
1.06383
5
4
F = UD = (I – Q)-1D = 1
0.18698
0.81302
2
0.10568
0.89432
3
0.04255
0.95745
The expected total cost of an item sold is equal to
1
1192.185
4.5c) UqT = 2
936.404
3
531.9149
(Uq)1 = 1192.185
4.5d)
State
v(2) = 0
v(1) = q+
P v(2)
v(0) = q+
P v(1)
5
0
60
120
4
0
20
40
1
0
300
660.8
2
0
400
864.6
3
0
500
550.4