10
Anomaly Detection
1. Compare and contrast the different techniques for anomaly detection that
were presented in Section 10.1.2. In particular, try to identify circumstances
in which the definitions of anomalies used in the different techniques might
be equivalent or situations in which one might make sense, but another would
not. Be sure to consider different types of data.
First, note that the proximity- and density-based anomaly detection tech-
niques are related. Specifically, high density in the neighborhood of a point
On the other hand, the proximity- and density-based approaches do not
make any particular assumption about the data, although the definition of
an anomaly does vary from one proximity- or density-based technique to
another. Proximity-based approaches can be used for virtually any type
2. Consider the following definition of an anomaly: An anomaly is an object
that is unusually influential in the creation of a data model.
(a) Compare this definition to that of the standard model-based definition
of an anomaly.
(b) For what sizes of data sets (small, medium, or large) is this definition
appropriate?
3. In one approach to anomaly detection, objects are represented as points in
a multidimensional space, and the points are grouped into successive shells,
where each shell represents a layer around a grouping of points, such as a
convex hull. An object is an anomaly if it lies in one of the outer shells.
(a) To which of the definitions of an anomaly in Section 10.1.2 is this defi-
nition most closely related?
(b) Name two problems with this definition of an anomaly.
i. For the convex hull approach, the distance of the points in a con-
4. Association analysis can be used to find anomalies as follows. Find strong as-
sociation patterns, which involve some minimum number of objects. Anoma-
lies are those objects that do not belong to any such patterns. To make this
more concrete, we note that the hyperclique association pattern discussed in
Section 6.8 is particularly suitable for such an approach. Specifically, given a
user-selected h-confidence level, maximal hyperclique patterns of objects are
159
found. All objects that do not appear in a maximal hyperclique pattern of
at least size three are classified as outliers.
(a) Does this technique fall into any of the categories discussed in this
chapter? If so, which one?
(b) Name one potential strength and one potential weakness of this ap-
proach.
Strengths of this approach are that (1) the objects that do not belong to
any size 3 hyperclique are not strongly connected to other objects and
5. Discuss techniques for combining multiple anomaly detection techniques to
improve the identification of anomalous objects. Consider both supervised
and unsupervised cases.
In the supervised case, we could use ensemble classification techniques. In
6. Describe the potential time complexity of anomaly detection approaches
based on the following approaches: model-based using clustering, proximity-
based, and density. No knowledge of specific techniques is required. Rather,
focus on the basic computational requirements of each approach, such as the
time required to compute the density of each object.
If K-means clustering is used, then the complexity is dominated by finding
the clusters. This requires time proportional to the number of objects, i.e.,
160 Chapter 10 Anomaly Detection
7. The Grubbs’ test, which is described by Algorithm 10.1, is a more statistically
sophisticated procedure for detecting outliers than that of Definition 10.3. It
is iterative and also takes into account the fact that the z-score does not
have a normal distribution. This algorithm computes the z-score of each
value based on the sample mean and standard deviation of the current set of
values. The value with the largest magnitude z-score is discarded if its z-score
is larger than gc, the critical value of the test for an outlier at significance
level α. This process is repeated until no objects are eliminated. Note that
the sample mean, standard deviation, and gcare updated at each iteration.
Algorithm 10.1 Grubbs’ approach for outlier elimination.
1: Input the values and α
{mis the number of values, αis a parameter, and tcis a value chosen so that
α=prob(x≥tc)foratdistribution with m−2 degrees of freedom.}
2: repeat
3: Compute the sample mean (x) and standard deviation (sx).
4: Compute a value gcso that prob(|z|≥gc)=α.
(In terms of tcand m,gc=m−1
√mt2
c
m−2+t2
c.)
5: Compute the z-score of each value, i.e., z=(x−x)/sx.
6: Let g=max|z|, i.e., find the z-score of largest magnitude and call it g.
7: if g>g
cthen
8: Eliminate the value corresponding to g.
9: m←m−1
10: end if
11: until No objects are eliminated.
(a) What is the limit of the value m−1
√mt2
c
m−2+t2
cused for Grubbs’ test as
mapproaches infinity? Use a significance level of 0.05.
161
For m=10
(b) Describe, in words, the meaning of the previous result.
8. Many statistical tests for outliers were developed in an environment in which
a few hundred observations was a large data set. We explore the limitations
of such approaches.
(a) For a set of 1,000,000 values, how likely are we to have outliers according
to the test that says a value is an outlier if it is more than three standard
deviations from the average? (Assume a normal distribution.)
(b) Does the approach that states an outlier is an object of unusually low
probability need to be adjusted when dealing with large data sets? If
so, how?
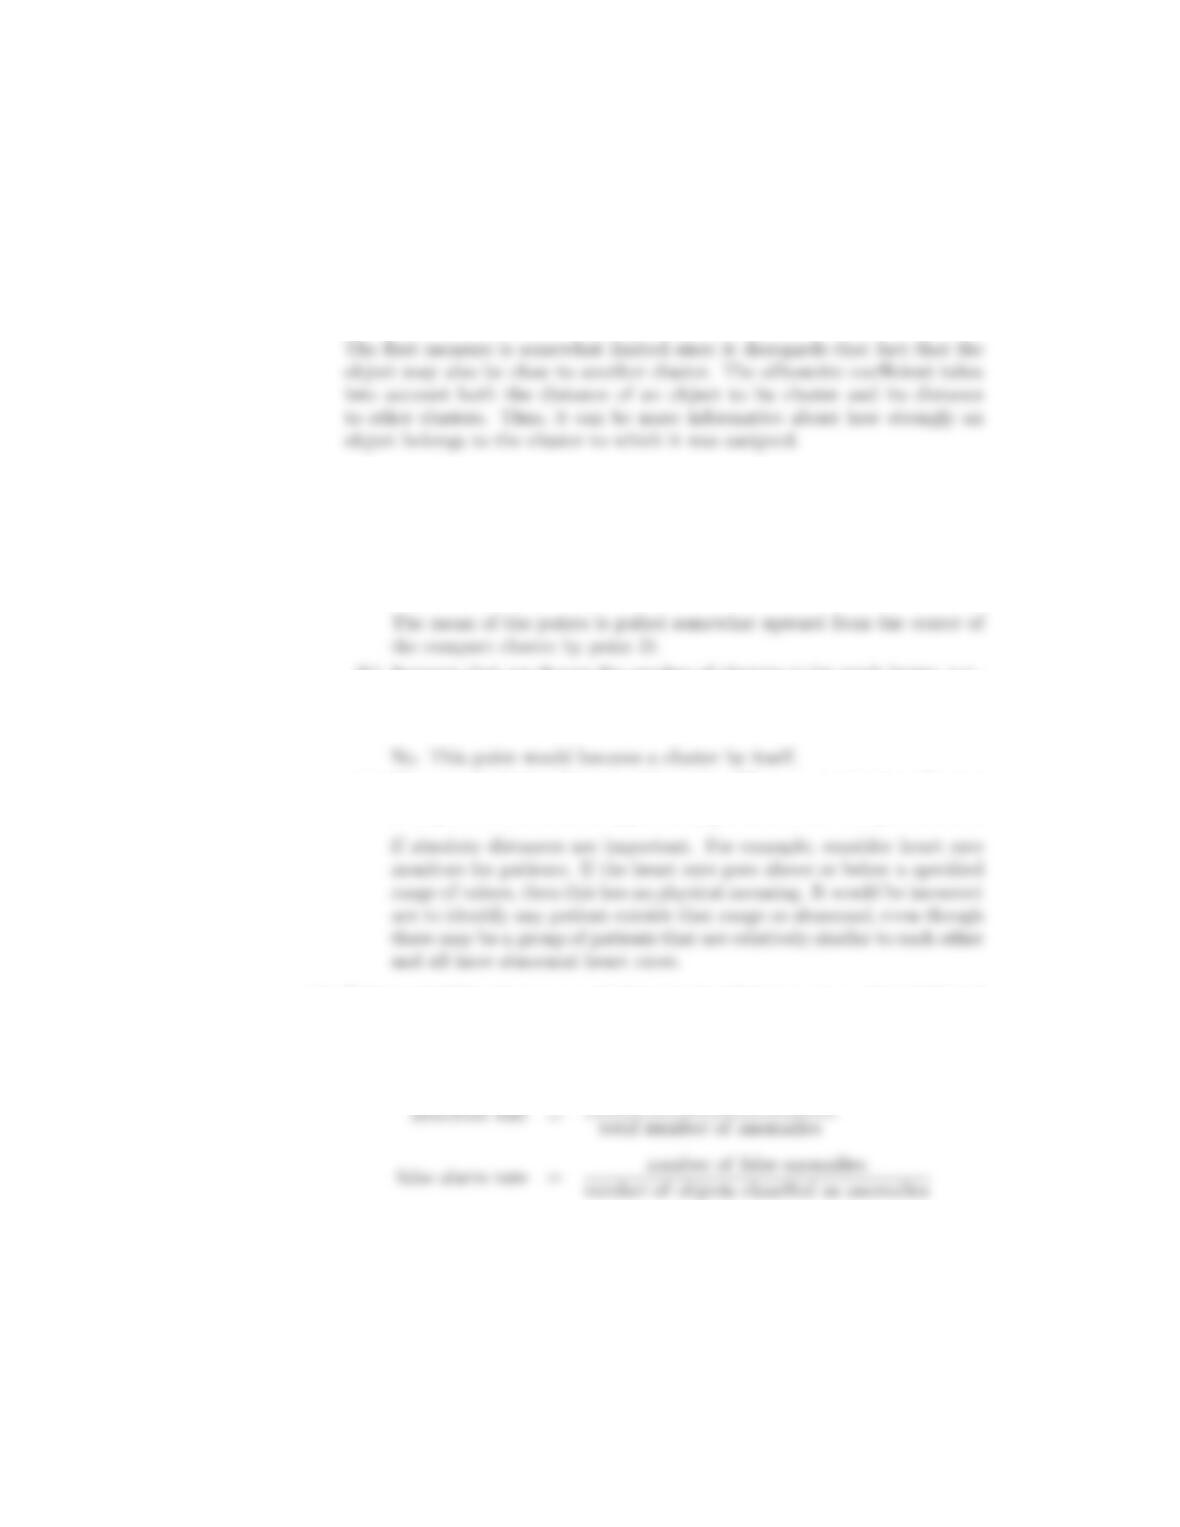
9. The probability density of a point xwith respect to a multivariate normal
distribution having a mean μand covariance matrix Σis given by the equa-
(√2π)m|Σ|1/2e−(x−μ)Σ−1(x−μ)T
Using the sample mean xand covariance matrix Sas estimates of the mean
μand covariance matrix Σ, respectively, show that the log(prob(x)) is equal
to the Mahalanobis distance between a data point xand the sample mean x
plus a constant that does not depend on x.
162 Chapter 10 Anomaly Detection
The constant and the constant factor do not affect the ordering of this quan-
tity, only their magnitude. Thus, if we want to base a distance on this
quantity, we can keep only the variable part, which is the Mahalanobis dis-
tance.
10. Compare the following two measures of the extent to which an object belongs
to a cluster: (1) distance of an object from the centroid of its closest cluster
and (2) the silhouette coefficient described in Section 8.5.2.
11. Consider the (relative distance) K-means scheme for outlier detection de-
scribed in Section 10.5 and the accompanying figure, Figure 10.10.
(a) The points at the bottom of the compact cluster shown in Figure 10.10
have a somewhat higher outlier score than those points at the top of
the compact cluster. Why?
(b) Suppose that we choose the number of clusters to be much larger, e.g.,
10. Would the proposed technique still be effective in finding the most
extreme outlier at the top of the figure? Why or why not?
(c) The use of relative distance adjusts for differences in density. Give an
example of where such an approach might lead to the wrong conclusion.
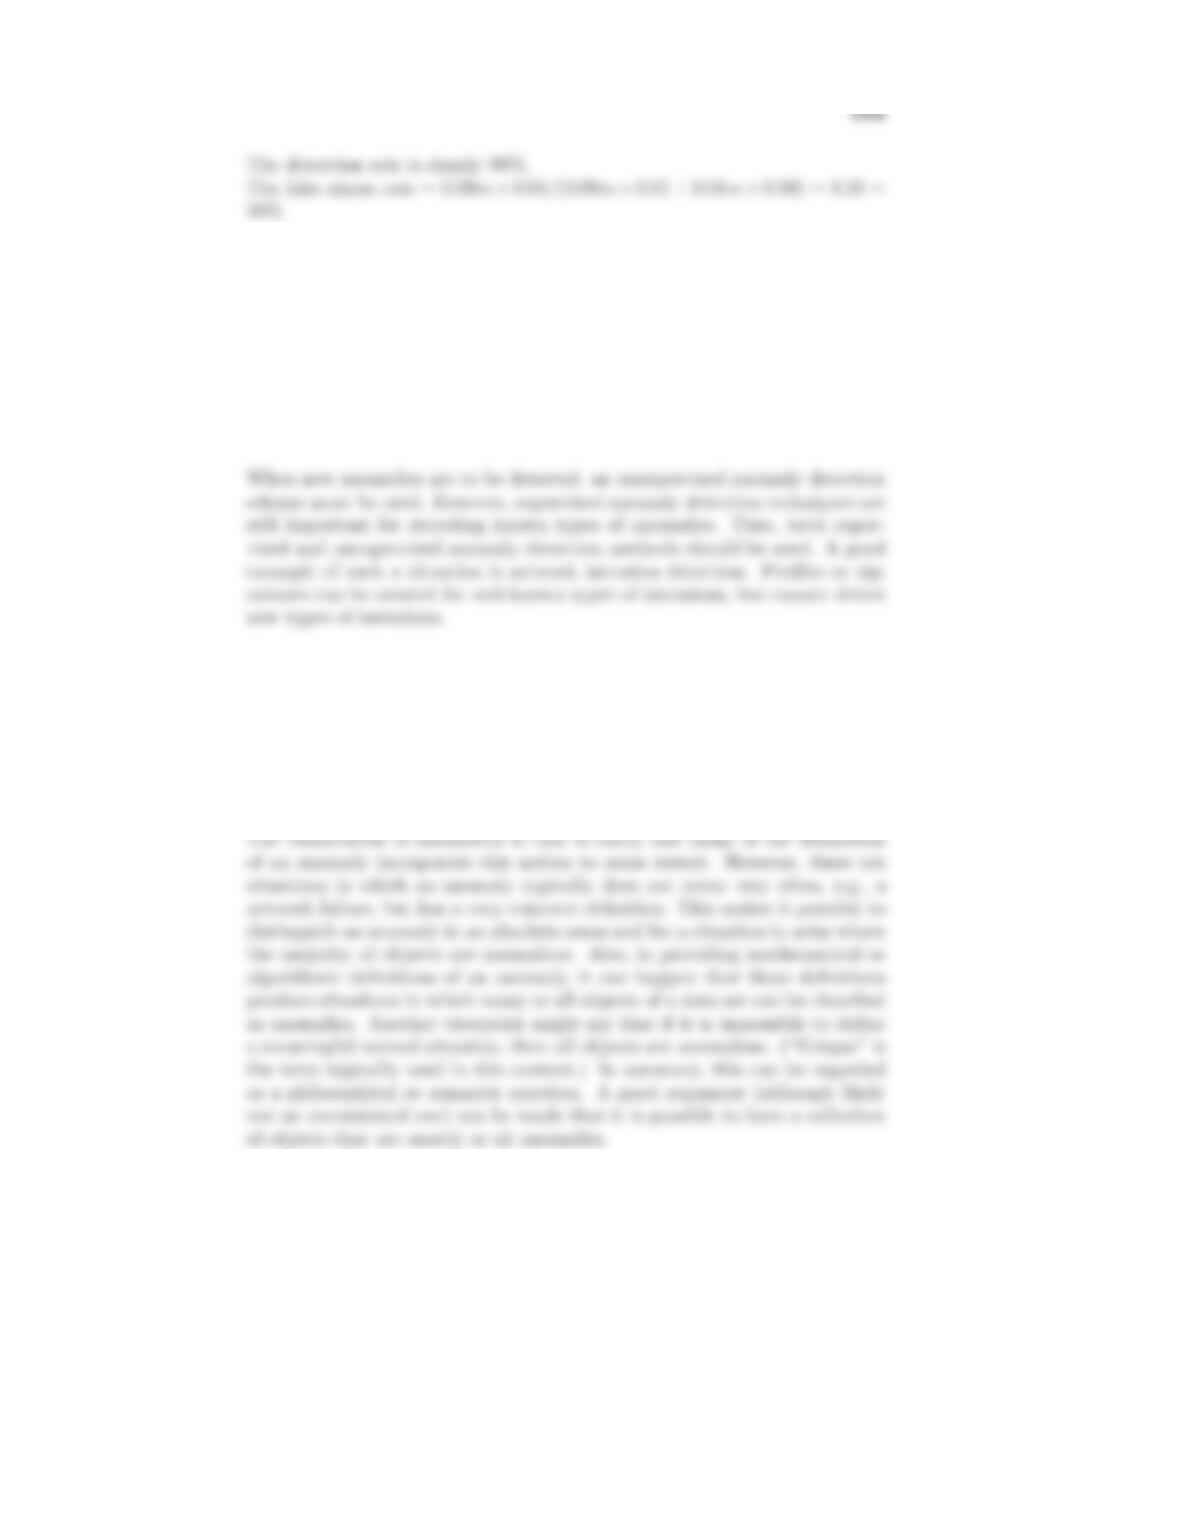
12. If the probability that a normal object is classified as an anomaly is 0.01 and
the probability that an anomalous object is classified as anomalous is 0.99,
then what is the false alarm rate and detection rate if 99% of the objects are
normal? (Use the definitions given below.)
13. When a comprehensive training set is available, a supervised anomaly detec-
tion technique can typically outperform an unsupervised anomaly technique
when performance is evaluated using measures such as the detection and false
alarm rate. However, in some cases, such as fraud detection, new types of
anomalies are always developing. Performance can be evaluated according
to the detection and false alarm rates, because it is usually possible to de-
termine, upon investigation, whether an object (transaction) is anomalous.
Discuss the relative merits of supervised and unsupervised anomaly detection
under such conditions.
14. Consider a group of documents that has been selected from a much larger
set of diverse documents so that the selected documents are as dissimilar
from one another as possible. If we consider documents that are not highly
related (connected, similar) to one another as being anomalous, then all of
the documents that we have selected might be classified as anomalies. Is it
possible for a data set to consist only of anomalous objects or is this an abuse
of the terminology?
15. Consider a set of points, where most points are in regions of low density, but
a few points are in regions of high density. If we define an anomaly as a point
in a region of low density, then most points will be classified as anomalies.
Is this an appropriate use of the density-based definition of an anomaly or
should the definition be modified in some way?
16. Consider a set of points that are uniformly distributed on the interval [0,1].
Is the statistical notion of an outlier as an infrequently observed value mean-
ingful for this data?
17. An analyst applies an anomaly detection algorithm to a data set and finds
a set of anomalies. Being curious, the analyst then applies the anomaly
detection algorithm to the set of anomalies.
(a) Discuss the behavior of each of the anomaly detection techniques de-
scribed in this chapter. (If possible, try this for real data sets and
algorithms.)
(b) What do you think the behavior of an anomaly detection algorithm
should be when applied to a set of anomalous objects?
BIBLIOGRAPHY 165
Bibliography
[1] W. W. Cohen. Fast effective rule induction. In Proc. of the 12th Intl. Conf. on Machine
Learning, pages 115–123, Tahoe City, CA, July 1995.
[2] S. Cost and S. Salzberg. A weighted nearest neighbor algorithm for learning with