16 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
value pairs. The reduction step then combines those tuples to produce the
results of the MapReduce task.
17.5 Q5: Which of the following statements about MapReduce is false
a. In the MapReduce step, Hadoop divides the data into batches that it distributes
across the nodes in the cluster.
b. Hadoop also distributes the MapReduce task’s code to the nodes in the cluster
and executes the code on one node at a time sequentially. Each node processes
only the batch of data stored on that node.
c. The reduction step combines the results from all the nodes to produce the final
result.
d. To coordinate all this, Hadoop uses YARN (“yet another resource negotiator”)
to manage all the resources in the cluster and schedule tasks for execution.
17.5 Q6: Which Hadoop ecosystem technology is described by “SQL querying of
non-relational data in Hadoop and NoSQL databases.”
a. Ambari
b. Drill
c. Flume
d. HBase
17.5 Q7: Which of the following Hadoop ecosystem technologies is described by
“real-time messaging, stream processing and storage, typically to transform and
process high-volume streaming data, such as website activity and streaming IoT
data.”
a. Hive
b. Impala
c. Kafka
d. Pig
17.5 Q8: Which Hadoop ecosystem technology is described by “A service for
managing cluster configurations and coordination between clusters?”
a. Sqoop
b. Storm
c. ZooKeeper
d. None of the above
17.8 Internet of Things and Dashboards 17
© Copyright 2020 by Pearson Education, Inc. All Rights Reserved.
Answer: c.
17.5 Q9: Which of the following statements a), b) or c) is false?
a. Numerous cloud vendors provide Hadoop as a service.
b. In addition, companies like Cloudera and Hortonworks (recently merged) offer
integrated Hadoop-ecosystem components and tools via the major cloud vendors.
c. Cloudera and Hortonworks also offer free downloadable environments that you
can run on the desktop for learning, development and testing before you commit
to cloud-based hosting, which can incur significant costs.
d. All of the above statements are true.
17.5.2 Creating an Apache Hadoop Cluster in Microsoft Azure
HDInsight
17.5 Q10: Which of the following statements a), b) or c) is false?
a. Most major cloud vendors have support for Hadoop and Spark computing clus-
ters that you can configure to meet your application’s requirements.
b. Multi-node cloud-based clusters typically are free services.
c. Microsoft Azure’s HDInsight service provides Hadoop capabilities.
d. All of the above statements are true.
17.5.3 Hadoop Streaming
17.5 Q11: Which of the following statements a), b) or c) is false?
a. For languages like Python that are not natively supported in Hadoop, you must
use Hadoop streaming to implement your tasks.
b. In Hadoop streaming, the Python scripts that implement the mapping and re-
duction steps use network sockets to communicate with Hadoop.
c. Usually, the standard input stream reads from the keyboard and the standard
output stream writes to the command line. However, these can be redirected (as
Hadoop does) to read from other sources and write to other destinations.
d. All of the above statements are true.
17.5 Q12: Hadoop streaming uses the standard input and standard output
streams as follows:
18 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
a. Hadoop supplies the input to the mapping script—called the mapper. This
script reads its input from the standard input stream. The mapper writes its re-
sults to the standard output stream.
b. Hadoop supplies the mapper’s output as the input to the reduction script—
called the reducer—which reads from the standard input stream.
c. The reducer writes its results to the standard output stream. Hadoop writes the
reducer’s output to the Hadoop file system (HDFS).
d. All of the above statements are true.
17.5.4 Implementing the Mapper
17.5 Q13: Which of the following statements a), b) or c) is false?
a. By default, Hadoop expects the mapper’s output and the reducer’s input and
output to be in the form of key–value pairs separated by a tab.
b. In a mapper script, the notation #!/usr/bin/env python3 tells Hadoop to
execute the Python code using python3. This line must come before all other
comments and code in the file.
c. At the time of this writing, Microsoft HDInsight clusters contain Python 2.7.12
and Python 3.5.2, so you can use f-strings in your code.
d. All of the above statements are true.
17.5 Q14: Consider the following mapper code:
1 #!/usr/bin/env python3
2 # length_mapper.py
3 “””Maps lines of text to key-value pairs of word lengths and 1.”””
4 import sys
5
6 def tokenize_input():
7 “””Split each line of standard input into a list of strings.”””
8 for line in sys.stdin:
9 yield line.split()
10
11 # read each line in the the standard input and for every word
12 # produce a key-value pair containing the word, a tab and 1
13 for line in tokenize_input():
14 for word in line:
15 print(str(len(word)) + ‘\t1’)
Which of the following statements a), b) or c) is false.
17.8 Internet of Things and Dashboards 19
a. Generator function tokenize_input reads lines of text from the standard in-
put stream and for each returns a list of strings.
b. When Hadoop executes the script, lines 13–15 iterate through the lists of
strings from tokenize_input. For each list (line) and for every string (word)
in that list, the script outputs a key–value pair with the word’s length as the key,
a tab (\t) and the value 1, indicating that there is one word (so far) of that length.
Of course, there probably are many words of that length.
c. The MapReduce algorithm’s reduction step will summarize these key–value
pairs.
d. All of the above statements are true.
17.5.5 Implementing the Reducer
17.5 Q15: Consider the following reducer code:
1 #!/usr/bin/env python3
2 # length_reducer.py
3 “””Counts the number of words with each length.”””
4 import sys
5 from itertools import groupby
6 from operator import itemgetter
7
8 def tokenize_input():
9 “””Split each line of standard input into a key and a value.”””
10 for line in sys.stdin:
11 yield line.strip().split(‘\t’)
12
13 # produce key-value pairs of word lengths and counts separated by tabs
14 for word_length, group in groupby(tokenize_input(), itemgetter(0)):
15 try:
16 total = sum(int(count) for word_length, count in group)
17 print(word_length + ‘\t’ + str(total))
18 except ValueError:
19 pass # ignore word if its count was not an integer
Which of the following statements a), b) or c) is false?
a. Function tokenize_input is a generator function that reads and splits the
key–value pairs produced by the mapper.
b. The mapper script sends its output directly to the reducer script.
c. For each line, tokenize_input strips any leading or trailing whitespace (such
as the terminating newline) and yields a list containing the key and a value.
d. All of the above statements are true.
20 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
© Copyright 2020 by Pearson Education, Inc. All Rights Reserved.
Answer: b. Actually, the mapper sends its output to the standard output
stream, which Hadoop Streaming then uses as input to the reducer script.
17.5 Q16: Consider the following reducer code:
1 #!/usr/bin/env python3
2 # length_reducer.py
3 “””Counts the number of words with each length.”””
4 import sys
5 from itertools import groupby
6 from operator import itemgetter
7
8 def tokenize_input():
9 “””Split each line of standard input into a key and a value.”””
10 for line in sys.stdin:
11 yield line.strip().split(‘\t’)
12
13 # produce key-value pairs of word lengths and counts separated by tabs
14 for word_length, group in groupby(tokenize_input(), itemgetter(0)):
15 try:
16 total = sum(int(count) for word_length, count in group)
17 print(word_length + ‘\t’ + str(total))
18 except ValueError:
19 pass # ignore word if its count was not an integer
Which of the following statements a), b) or c) is false?
a. When the MapReduce algorithm executes this reducer, lines 14–19 use the
groupby function from the itertools module to group all word lengths of the
same value. The first argument calls tokenize_input to get the lists represent-
ing the key–value pairs. The second argument indicates that the key–value pairs
should be grouped based on the element at index 0 in each list—that is the key.
b. Line 16 totals all the counts for a given key. Line 17 outputs a new key–value
pair consisting of the word length and the total number of words of that length.
c. The MapReduce algorithm takes all the final word length and count outputs and
writes them to a file in HDFS—the Hadoop file system.
d. All of the above statements are true.
17.5.6 Preparing to Run the MapReduce Example
No questions
17.8 Internet of Things and Dashboards 21
17.5.7 Running the MapReduce Job
No questions
17.6 Spark
17.6.1 Spark Overview
17.6 Q1: Which of the following statements a), b) or c) is false?
a. When you process truly big data, performance is crucial.
b. Spark is geared to disk-based batch processing—reading the data from disk,
processing the data and writing the results back to disk.
c. Many big-data applications demand better performance than is possible with
disk-intensive operations. In particular, fast streaming applications that require
either real-time or near-real-time processing won’t work in a disk-based archi-
tecture.
d. All of the above statements are true.
17.6 Q2: Which of the following statements is false?
a. Spark was initially developed in 2009 at U. C. Berkeley and funded by DARPA
(the Defense Advanced Research Projects Agency).
b. Spark was created as a distributed execution engine for high-performance nat-
ural language processing.
c. Spark uses an in–memory architecture that “has been used to sort 100 TB of
data 3X faster than Hadoop MapReduce on 1/10th of the machines” and runs
some workloads up to 100 times faster than Hadoop.
d. Spark’s significantly better performance on batch-processing tasks is leading
many companies to replace Hadoop MapReduce with Spark.
17.6 Q3: Which of the following statements a), b) or c) is false?
a. For high-performance, Spark distributes the operations you specify in Python
to the cluster’s nodes for parallel execution. Spark streaming enables you to pro-
cess data as it’s received.
b. Pandas DataFrames enable you to view RDDs as a collection of named columns.
You can use pandas DataFrames with Spark SQL to perform queries on distrib-
uted data.
22 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
c. Spark also includes Spark MLlib (the Spark Machine Learning Library), which
enables you to perform machine-learning algorithms.
d. All of the above statements are true.
17.6 Q4: Which of the following statements a), b) or c) is false?
a. Hadoop providers typically also provide Spark support.
b. Databricks is a Spark-specific vendor—they provide a “zero-management
cloud platform built around Spark.” Their website also is an excellent resource
for learning Spark.
c. The paid Databricks platform runs on Amazon AWS or Microsoft Azure. Data-
bricks also provides a free Databricks Community Edition, which is a great way
to get started with both Spark and the Databricks environment.
d. All of the above statements are true.
17.6.2 Docker and the Jupyter Docker Stacks
17.6 Q5: Which of the following statements a), b) or c) is false?
a. Docker is a tool for packaging software into containers that bundle everything
required to execute that software across platforms.
b. Some software packages require complicated setup and configuration. For
many of these, there are preexisting Docker containers that you can download for
free and execute locally on your desktop or notebook computers.
c. You can create custom Docker containers that are configured with the versions
of every piece of software and every library you used in your study. This would
enable others to recreate the environment you used, then reproduce your work,
and will help you reproduce your results at a later time.
d. All of the above statements are true.
17.6 Q6: Which of the following statements a), b) or c) is false?
a. Every time you start a container with docker run, Docker gives you a new in-
stance that contains any libraries you installed previously.
b. The command
docker stop container_name
will shut down the specified container. The command
17.8 Internet of Things and Dashboards 23
docker restart container_name
will restart the specified container.
c. Docker also provides a GUI app called Kitematic that you can use to manage
your containers, including stopping and restarting them.
d. All of the above statements are true.
17.6.3 Word Count with Spark
17.6 Q7: Which of the following statements is false?
a. A SparkContext (from module pyspark) object gives you access to Spark’s
capabilities in Python.
b. Many Spark environments create the SparkContext for you, but in the Jupyter
pyspark-notebook Docker stack, you must create this object.
c. Threads enable a single node cluster to execute portions of the Spark tasks con-
currently to simulate the parallelism that Spark clusters provide.
d. When we say that two tasks are operating in parallel, we mean that they’re both
making progress at once—typically by executing a task for a short burst of time,
then allowing another task to execute. When we say that two tasks are operating
concurrently, we mean that they’re executing simultaneously, which is one of the
key benefits of Hadoop and Spark executing on cloud-based clusters of comput-
ers.
17.6 Q8: Which of the following statements a), b) or c) is false?
a. You work with a SparkContext using functional-style programming tech-
niques (like filtering, mapping and reduction) applied to a resilient distributed
dataset (RDD).
b. An RDD takes data stored throughout a cluster in the Hadoop file system and
enables you to specify a series of processing steps to transform the data in the
RDD.
c. The processing steps mentioned in Part (b) are greedy—the steps are per–
formed immediately in response to the method call.
d. All of the above statements are true.
24 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
© Copyright 2020 by Pearson Education, Inc. All Rights Reserved.
Answer: c. Actually, the processing steps are lazy—they are not performed
until a method is called that initiates all the processing steps (such as RDD
method collect).
17.6.4 Spark Word Count on Microsoft Azure
No questions.
17.7 Spark Streaming: Counting Twitter Hashtags
Using the pyspark-notebook Docker Stack
17.7 Q1: We created and ran a Spark streaming application which receives a
stream of tweets on the topic(s) you specify and summarizes the top-20 hashtags
in a bar chart that updates every 10 seconds. Which of the following statements
a), b) or c) is false?
a. One way for Spark streaming to receive data is via a network socket—a low-
level view of client/server networking in which a client app communicates with
a server app over a network.
b. Each socket represents one endpoint of a connection.
c. A program can read from a socket or write to a socket similarly to reading from
or writing to a SQL database.
d. All of the above statements are true.
17.7.1 Streaming Tweets to a Socket
17.7 Q2: Which of the following statements a), b) or c) is false?
a. The following code calls a socket object’s bind method with a tuple containing
the hostname or IP address of the computer and the port number on that com-
puter. Together these represent where an app should wait for an initial connec-
tion from another app:
client_socket.bind((‘localhost’, 9876))
b. A socket’s listen method causes the script to wait until a connection is re-
ceived, as in:
client_socket.listen() # wait for client to connect
17.8 Internet of Things and Dashboards 25
c. Once a client application connects, socket method accept accepts the connec-
tion. This method returns a tuple containing a new socket object that the script
will use to communicate with the client application and the IP address of the cli-
ent application’s computer.
connection, address = client_socket.accept()
d. All of the above statements are true.
17.7.2 Summarizing Tweet Hashtags; Introducing Spark SQL
17.7 Q3: Which of the following statements is false?
a. You can use SQL to query data in resilient distributed datasets (RDDs).
b. Spark SQL uses a Spark DataFrame to get a table view of the underlying RDDs.
c. A SparkSession (module pyspark.sql) is used to create a DataFrame from
an RDD. There can be only one SparkSession object per Spark application.
d. In Spark streaming, a DStream is a sequence of RDDs each representing a mini–
batch of data to process
17.7 Q4: Every RDD has access to the current SparkContext via the attribute
________.
a. cluster
b. broadcast
c. context
d. connection
17.7 Q5: To query a Spark DataFrame, you must first create a table view, which
enables Spark SQL to query the DataFrame like a table in a ________ database.
a. hierarchical
b. graph
c. key-value
d. relational
17.7 Q6: Which of the following statements a), b) or c) is false?
26 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
a. For Spark streaming, you must create a StreamingContext (from the module
pyspark.streaming), providing as arguments the SparkContext and how of-
ten in seconds to process batches of streaming data.
b. The following StreamingContext processes batches every 10 seconds—this
is the batch interval
ssc = StreamingContext(sc, 10)
c. Depending on how fast data is arriving, you may wish to shorten or lengthen
your batch intervals.
d. All of the above statements are true.
17.7 Q7: Which of the following statements is false?
a. By default, Spark streaming maintains state information as you process the
stream of RDDs.
b. You can use Spark checkpointing to keep track of the streaming state. Check-
pointing enables fault-tolerance for restarting a stream in cases of cluster node
or Spark application failures, and stateful transformations, such as summarizing
the data received so far—as we’re doing in this example.
c. StreamingContext method checkpoint sets up a checkpointing folder
where state information is stored, as in:
ssc.checkpoint(‘hashtagsummarizer_checkpoint’)
d. For a Spark streaming application in a cloud–based cluster, you’d specify a lo–
cation within HDFS to store the checkpoint folder.
17.7 Q10: StreamingContext’s ________ method begins the streaming process.
a. stream
b. start
c. start_stream
d. None of the above
17.8 Internet of Things and Dashboards
17.8 Q1: Which of the following statements a), b) or c) is false?
17.8 Internet of Things and Dashboards 27
a. In the late 1960s, the Internet began as the ARPANET, which initially connected
four universities and grew to 10 nodes by the end of 1970.
b. In the last 50 years, the Internet has grown to billions of computers,
smartphones, tablets and an enormous range of other device types connected to
the Internet worldwide.
c. Every device is a “thing” in the Internet of Things (IoT).
d. All of the above statements are true.
17.8 Q2: Which of the following statements reflect security, privacy and ethical
concerns associated with IoT?
a. Unsecured IoT devices have been used to perform distributed-denial–of-service
(DDOS) attacks on computer systems.
b. Home security cameras that you intend to protect your home could potentially
be hacked to allow others access to the video stream.
c. Children have accidentally ordered products on Amazon by talking to Alexa de-
vices, companies have created TV ads that would activate Google Home devices
by speaking their trigger words and causing Google Assistant to read Wikipedia
pages about a product to you. A judge recently ordered Amazon to turn over Alexa
recordings for use in a criminal case.
d. All of the above statements reflect these concerns.
17.8.1 Publish and Subscribe
17.8 Q3: Which of the following statements a), b) or c) is false?
a. IoT devices (and many other types of devices and applications) commonly com-
municate with one another and with applications via pub/sub (publisher/sub-
scriber) systems.
b. A publisher is any device or application that sends a message to a cloud-based
service, which in turn sends that message to all subscribers. Typically each pub-
lisher specifies a topic or channel, and each subscriber specifies one or more top-
ics or channels for which they’d like to receive messages.
c. Apache Kafka is a Hadoop ecosystem component that provides a high-perfor-
mance publish/subscribe service, real-time stream processing and storage of
streamed data.
d. All of the above statements are true.
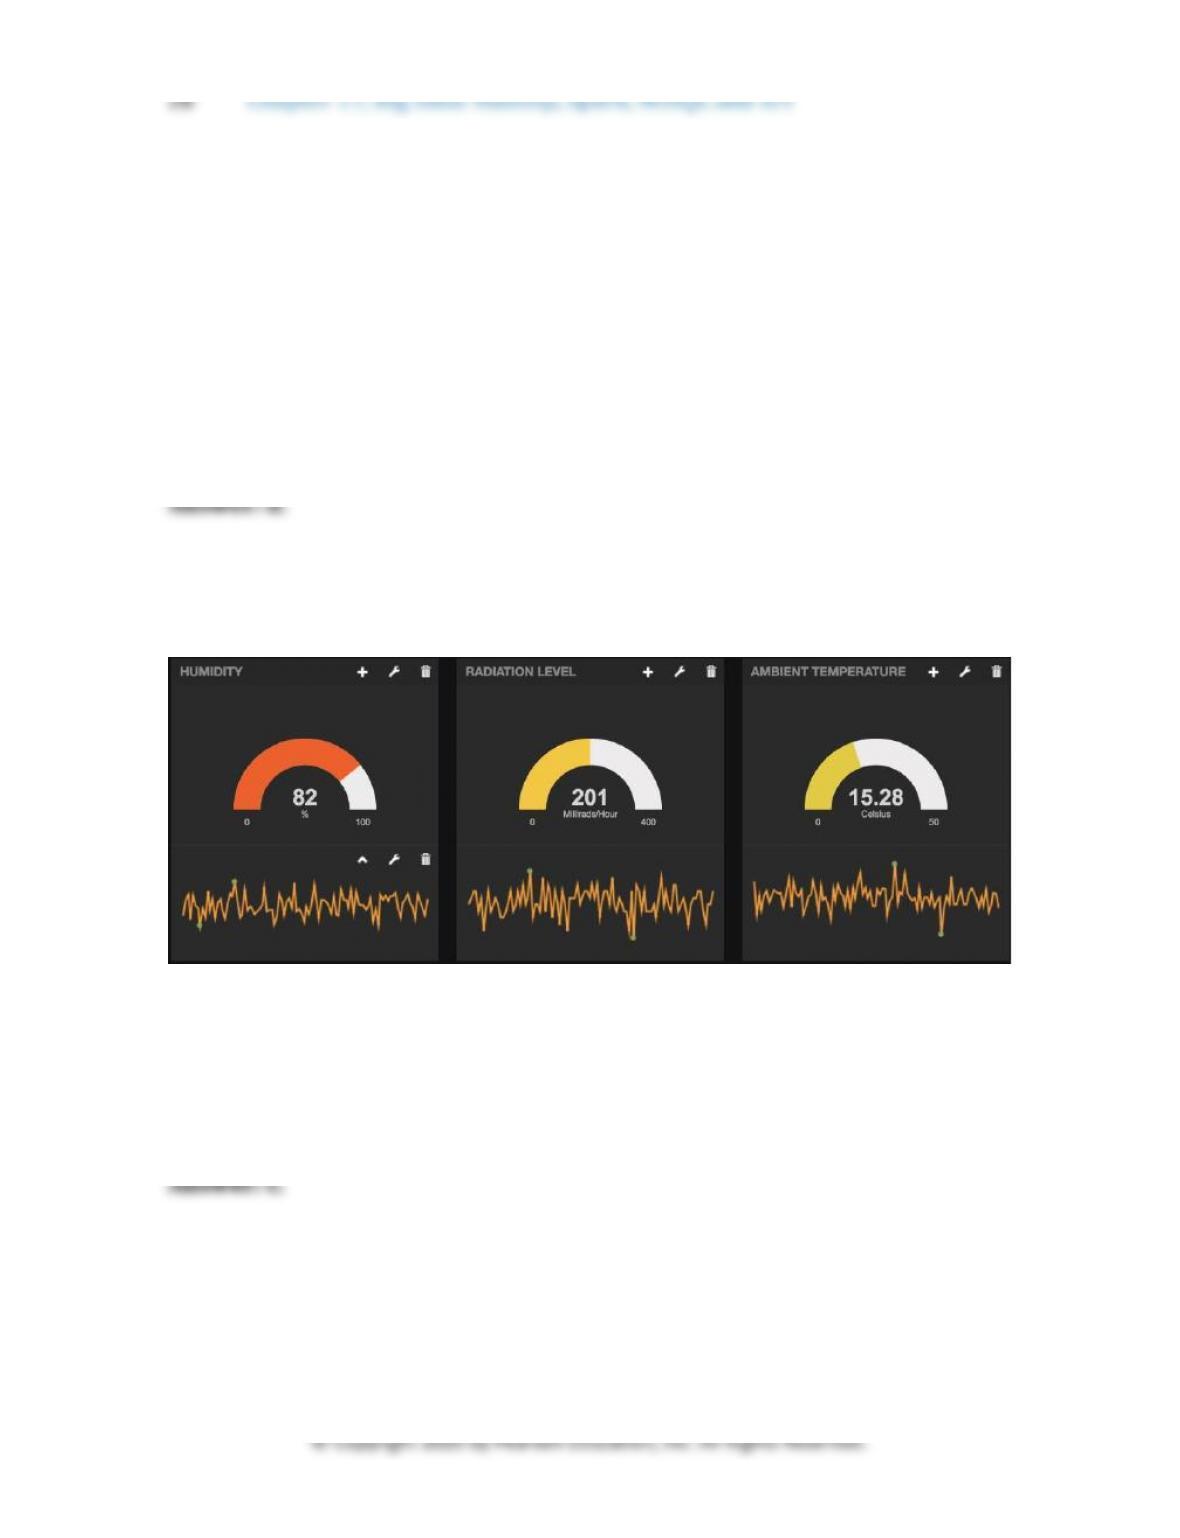
17.8 Internet of Things and Dashboards 29
b. The name “dweet” is based on “tweet”—a dweet is like a tweet, but from from
a device rather than a person.
c. By default, dweet.io is a public service, so any app can publish or subscribe to
messages.
d. All of the above statements are true.
17.8.4 Creating the Dashboard with Freeboard.io
No questions.
17.8.5 Creating a Python PubNub Subscriber
17.8 Q7: PubNub provides the ________ Python module for conveniently perform-
ing pub/sub operations.
a. pubsub
b. pubnub
c. subpub
d. None of the above.
17.7 Q12: When you subscribe to a PubNub stream, you must add a(n) ________
that receives status notifications and messages from the channel.
a. acceptor
b. auditor
c. listener
d. None of the above
17.7 Q13: The PubNub client uses a ________ key in combination with a channel
name to subscribe to a channel.
a. signature
b. subscription
c. connection
d. None of the above