Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT 1
Big Data: Hadoop, Spark, NoSQL
and IoT
17.1 Introduction
17.1 Q1: Which of the following statements is false?
a. Databases are critical big-data infrastructure for storing and manipulating the
massive amounts of data we’re creating.
b. Databases are critical for securely and confidentially maintaining that data, es-
pecially in the context of ever-stricter privacy laws such as HIPAA (Health Insur-
ance Portability and Accountability Act) in the United States and GDPR (General
Data Protection Regulation) for the European Union.
c. Relational databases store unstructured data in tables with a fixed-size number
of columns per row.
d. You’ll manipulate relational databases via Structured Query Language (SQL).
17.1 Q2: Which of the following statements a), b) or c) is false?
a. Most data produced today is unstructured data, like the content of Facebook
posts and Twitter tweets, or semi-structured data like JSON and XML documents.
b. Twitter processes each tweet’s contents into a semi-structured JSON document
with lots of metadata.
c. Relational databases are geared to the unstructured and semi-structured data
in big-data applications.
d. All of the above statements are true.
17.1 Q3: Which of the following statements a), b) or c) is false?
a. The four major types of NoSQL databases are key–value, document, columnar
and graph databases.
b. NoSQL databases blend the benefits of relational and NewSQL databases.
c. Many NoSQL and NewSQL vendors make it easy to get started with their prod-
ucts through free tiers and free trials, and typically in cloud-based environments
that require minimal installation and setup. This makes it practical for you to gain
big-data experience before “diving in.”
d. All of the above statements are true.
2 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
© Copyright 2020 by Pearson Education, Inc. All Rights Reserved.
Answer: b. Actually, NewSQL databases blend the benefits of relational and
NoSQL databases.
17.1 Q4: Which of the following statements a), b) or c) is false?
a. Much of today’s data is so large that it cannot fit on one system.
b. As big data grew, we needed distributed data storage and parallel processing
capabilities to process vast amounts of data more efficiently. This led to complex
technologies like Apache Hadoop for distributed data processing with massive
parallelism among clusters of computers where the intricate details are handled
for you automatically and correctly.
c. You can configure a multi-node Hadoop cluster using the Microsoft Azure HDIn-
sight cloud service, then use it to execute a Hadoop MapReduce job implemented
in Python.
d. All of the above statements are true.
17.1 Q5: Which of the following statements a), b) or c) is false?
a. As big-data processing needs grow, the information-technology community is
continually looking for ways to increase performance.
b. Spark was developed to perform certain big-data tasks more efficiently by
breaking them into pieces that do lots of disk I/O across many computers.
c. Spark streaming processes streaming data in mini-batches. Spark streaming
gathers data for a short time interval you specify, then gives you that batch of data
to process.
d. You can use Spark SQL to query data stored in a Spark DataFrame which, unlike
pandas DataFrames, may contain data distributed over many computers in a
cluster.
17.1 Q6: Which of the following statements a), b) or c) is false?
a. As data continues growing exponentially, we want to learn from that data and
do so at blazing speed.
b. Learning from big data requires sophisticated algorithms, hardware, software
and networking designs.
c. With more data, and especially with big data, machine learning can be even
more effective.
d. All of the above statements are true.
17.8 Internet of Things and Dashboards 3
17.2 Relational Databases and Structured Query
Language (SQL)
17.2 Q1: Which of the following statements is false?
a. A database is an integrated collection of data.
b. Database management systems allow for convenient access and storage of data
without concern for the internal representation of databases.
c. Relational database management systems (RDBMSs) store data in tables and
define relationships among the tables.
d. Table Query Language is used almost universally with relational database sys-
tems to manipulate data and perform queries, which request information that
satisfies given criteria.
17.2 Q2: Which of the following statements is false?
a. A relational database is a logical table-based representation of data that allows
the data to be accessed without consideration of its physical structure.
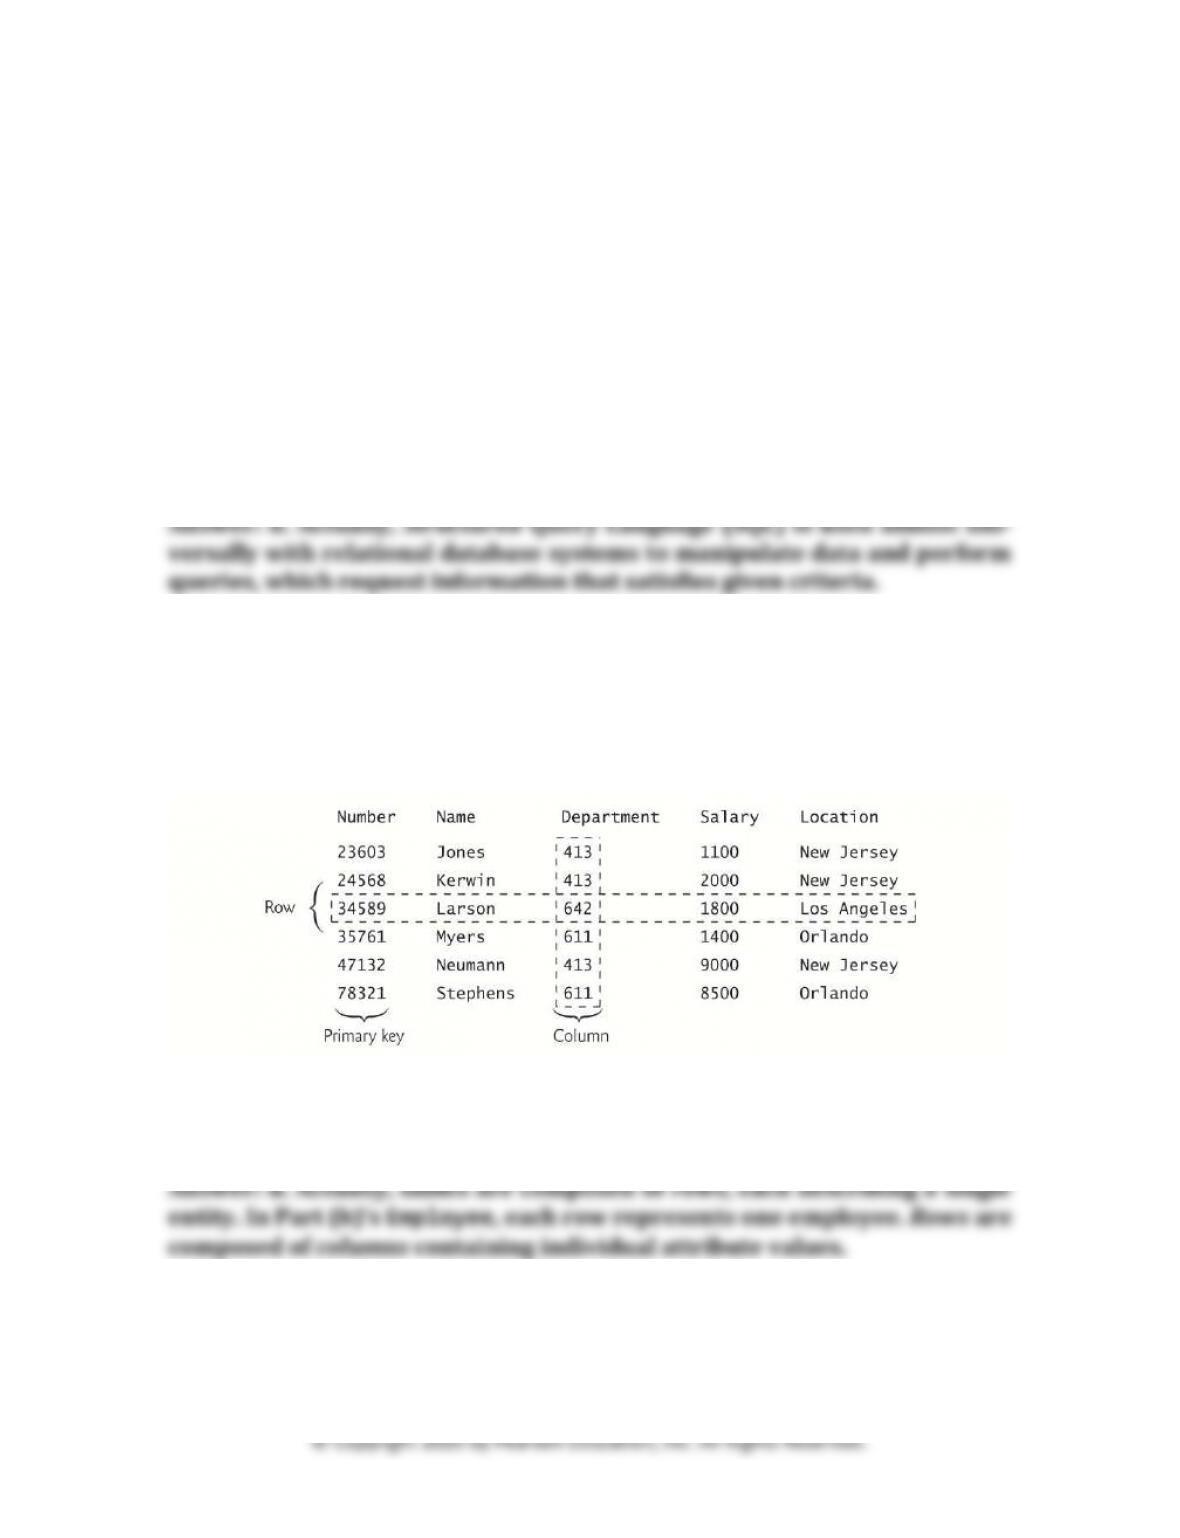
b. The following diagram shows a sample Employee table that might be used in a
personnel system:
c. Part (b)’s Employee table’s primary purpose is to store employees’ attributes.
d. Tables are composed of columns, each describing a single entity. In Part (b)’s
Employee table, each column represents one employee. Columns are composed
of rows containing individual attribute values.
17.2 Q3: Which of the following statements a), b) or c) is false?
a. A primary key is a column (or group of columns) with a value that’s unique for
each row. This guarantees that each row can be identified by its primary key.
4 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
b. Examples of primary keys are social security numbers, employee ID numbers
and part numbers in an inventory system—values in each of these are guaranteed
to be unique.
c. The rows of a relational database table are always listed in ascending order by
primary key.
d. All of the above statements are true.
17.2 Q4: Which of the following statements a), b) or c) is false?
a. Each column in a relational database table represents a different data attribute.
b. Columns are unique (by primary key) within a table, but particular row values
may be duplicated between columns.
c. Several rows in an Employee table’s Department column could contain the
same department number.
d. All of the above statements are true.
17.2 Q5: Which of the following statements a), b) or c) is false?
a. Different database users are often interested in different data and different re-
lationships among the data.
b. Most users require only subsets of a database table’s rows and columns.
c. You use Structured Query Language (SQL) to define queries. Queries specify
which subsets of the data to select from a table.
d. All of the above statements are true.
17.2 Q6: Which of the following statements a), b) or c) is false?
a. The open-source SQLite database management system is included with Python.
b. Only the SQLite database management system has Python support.
c. Each database management system that has Python support typically provides
a module that adheres to Python’s Database Application Programming Interface
(DB-API), which specifies common object and method names for manipulating
any database.
d. All of the above statements are true.
17.8 Internet of Things and Dashboards 5
17.2.1 A books Database
17.2 Q7: In the SQL query:
SELECT * FROM authors
the asterisk (*) is a ________ indicating that the query should get all the columns
from the authors table.
a. potpourri character
b. catchall
c. wildcard
d. None of the above
17.2 Q8: In SQL, a foreign key is a column in one table that matches a ________
column in another table.
a. domestic key
b. candidate key
c. primary key
d. None of the above
17.2 Q9: A goal when designing a relational database is to minimize data ________
among the tables.
a. dependency
b. binding
c. duplication
d. None of the above
17.2 Q10: In a relational database, every foreign-key value must appear as the
primary-key value in a row of another table so the DBMS can ensure that the for-
eign-key value is valid. This is known as the ________.
a. Rule of Entity Integrity
b. Rule of Referential Integrity
c. Rule of Guaranteed Access
d. None of the above
17.2.2 SELECT Queries
No questions.
17.8 Internet of Things and Dashboards 7
© Copyright 2020 by Pearson Education, Inc. All Rights Reserved.
Answer: d.
17.2.6 INSERT INTO Statement
17.2 Q14: Which of the following statements is false?
a. SQL can be used only to retrieve data from a relational database.
b. The pandas method read_sql uses a Cursor behind the scenes to execute que-
ries and access the rows of the results.
c. The INSERT INTO statement inserts a row into a table.
d. The SQL keywords INSERT INTO are followed by the table in which to insert
the new row and a comma-separated list of column names in parentheses.
17.2.7 UPDATE Statement
17.2 Q15: Which of the following statements is false?
a. An UPDATE statement modifies existing values in a table.
b. The UPDATE keyword is followed by the table to update, the keyword SET and
a comma-separated list of column_name : value pairs indicating the columns to
change and their new values.
c. An UPDATE’s change will be applied to every row if you do not specify a WHERE
clause. To make a change to only one row, it’s best to use the row’s unique pri-
mary key in the WHERE clause.
d. For statements that modify the database, the Cursor object’s rowcount attrib-
ute contains an integer value representing the number of rows that were modi-
fied. If this value is 0, no changes were made.
17.2.8 DELETE FROM Statement
No questions.
17.8 Internet of Things and Dashboards 9
a. The four NoSQL database categories are hierarchical, document, columnar (also
called column-based) and graph.
b. NewSQL databases blend features of relational and NoSQL databases.
c. We presented a case study in which we stored and manipulated a large number
of JSON tweet objects in a NoSQL document database, then summarized the data
in an interactive visualization displayed on a Folium map of the United States.
d. All of the above statements are true.
17.3.1 NoSQL Key–Value Databases
17.3 Q5: Which of the following statements a), b) or c) is false?
a. Like Python dictionaries, key–value databases store key–value pairs, but
they’re optimized for distributed systems and big-data processing.
b. For performance, key–value databases tend to replicate data in multiple cluster
nodes.
c. Some key–value databases are implemented in memory for performance, and
others store data on disk.
d. All of the above statements are true.
17.3.2 NoSQL Document Databases
17.3 Q6: Which of the following statements a), b) or c) is false?
a. A document database stores semi-structured data, such as JSON or XML docu-
ments.
b. In document databases, you typically add indexes for specific attributes, so you
can more efficiently locate and manipulate documents.
c. The most popular document database (and most popular overall NoSQL data-
base) is Neo4j.
d. All of the above statements are true.
17.3.3 NoSQL Columnar Databases
17.3 Q7: Which of the following statements about columnar databases a), b) or
c) is false?
a. A columnar database is similar to a relational database, but it stores unstruc-
tured data in columns rather than rows.
10 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
b. Because all of a column’s elements are stored together, selecting all the data for
a given column is more efficient.
c. Consider our authors table in the books database:
first last
id
1 Paul Deitel
2 Harvey Deitel
3 Abbey Deitel
4 Dan Quirk
5 Alexander Wald
If we consider each row as a Python tuple, the rows would be represented as (1,
‘Paul’, ‘Deitel’), (2, ‘Harvey’, ‘Deitel’), etc. In a columnar database,
all the values for a given column would be stored together, as in (1, 2, 3, 4, 5),
(‘Paul’, ‘Harvey’, ‘Abbey’, ‘Dan’, ‘Alexander’) and (‘Deitel’, ‘De-
itel’, ‘Deitel’, ‘Quirk’, ‘Wald’).
d. All of the above statements are true.
17.3.4 NoSQL Graph Databases
17.3 Q8: Which of the following statements a), b) or c) about graph databases is
false?
a. A graph database models relationships between objects.
b. The objects are called nodes (or vertices) and the relationships are called edges.
c. Edges are bidirectional.
d. All of the above statements are true.
17.3 Q9: Which of the following statements a), b) or c) is false?
a. A graph database stores nodes, edges and their attributes. If you use social net-
works, like Instagram, Snapchat, Twitter and Facebook, consider your social
graph, which consists of the people you know (nodes) and the relationships be-
tween them (edges). Every person has their own social graph, and these are in-
terconnected.
b. The famous “six degrees of separation” problem says that any two people in the
world are connected to one another by following a maximum of six edges in the
worldwide social graph.
c. Facebook’s algorithms use the social graphs of their billions of users to deter-
mine which stories should appear in each user’s news feed.
17.8 Internet of Things and Dashboards 11
d. All of the above statements are true.
17.3.5 NewSQL Databases
17.3 Q10: Relational databases typically use ACID (Atomicity, Consistency, Isola-
tion, Durability) transactions. Which of the following ACID attributes is described
by: “ensures that concurrent transactions occur as if they were performed se-
quentially?”
a. Atomicity
b. Consistency
c. Isolation
d. Durability
17.3 Q11: Relational databases typically use ACID (Atomicity, Consistency, Isola-
tion, Durability) transactions. Which of the following ACID attributes is described
by: “ensures that the database is modified only if all of a transaction’s steps are
successful?”
a. Atomicity
b. Consistency
c. Isolation
d. Durability
17.3 Q12: Which of the following statements a), b) or c) is false.
a. The types of applications that use NoSQL databases typically do not require the
guarantees that ACID-compliant databases provide.
b. Many NoSQL databases typically adhere to the BASE (Basic Availability, Soft–
state, Eventual consistency) model, which focuses more on the database’s availa-
bility.
c. Whereas BASE databases guarantee consistency when you write to the data-
base, ACID databases provide consistency at some later point in time.
d. All of the above statements are true.
17.8 Internet of Things and Dashboards 13
from pymongo import MongoClient
atlas_client = MongoClient(keys.mongo_connection_string)
b. The following code uses a pymongo MongoClient to get a pymongo Database
object representing a senators database, creating the database if it does not ex-
ist:
db = atlas_client.senators
c. Before storing JSON objects in a collection of a MongoDB database, you must
explicitly create the collection.
d. All of the above statements are true.
17.4 Q5: Which of the following statements about text searching in MongoDB is
false?
a. To text search in MongoDB, you must create a text index for the collection. This
specifies which document field(s) to search.
b. Each text index is defined as a tuple containing the field name to search and the
index type (‘text_index’).
c. MongoDB’s wildcard specifier $** indicates that every text field in a document
should be indexed for a full-text search.
d. Once an index is defined for a Collection, you can use its count_documents
method to count the total number of documents in the collection that contain the
specified text.
17.4 Q6: Which of the following statements is false?
a. Pandas DataFrame method groupby groups data by a specified column’s val-
ues, as in:
tweets_counts_by_state = tweet_counts_df.groupby(
‘State’, as_index=False).sum()
b. The as_index=False keyword argument in Part (a) indicates that the values
on which grouping was performed (‘State’ in this case) should be values in a
row of the resulting GroupBy object, rather than the indices for the columns.
c. The GroupBy object’s sum method, which is called at the end of the snippet in
Part (a), totals the GroupBy object’s numeric data by ‘State’.
d. All of the above statements are true.
14 Chapter 17, Big Data: Hadoop, Spark, NoSQL and IoT
© Copyright 2020 by Pearson Education, Inc. All Rights Reserved.
Answer: b. Actually, the as_index=False keyword argument indicates that
the state codes should be values in a column of the resulting GroupBy object,
rather than the indices for the rows.
17.4 Q7: A ________ shades areas in a Folium map using the values you specify to
determine color.
a. chromatic
b. choropleth
c. variagator
d. None of the above
17.4 Q8: A JSON dialect called ________ describes the boundaries of shapes such as
countries, states, etc. for use in maps.
a. BoundaryJSON
b. GeoJSON
c. TopographyJSON
d. None of the above
17.5 Hadoop
No questions.
17.5.1 Hadoop Overview
17.5 Q1: Which of the following statements a), b) or c) is false?
a. When Google was launched in 1998, there were approximately 2.4 million web-
sites—truly big data at the time. Today there are now nearly two billion websites
(almost a thousandfold increase since 1998).
b. When Google was developing their search engine, they knew that they needed
to return search results quickly. The only practical way to do this was to store and
index the entire Internet using a clever combination of secondary storage and
main memory.
c. Popular computers of that time couldn’t hold that amount of data and could not
analyze that amount of data fast enough to guarantee prompt search-query re-
sponses.
d. All of the above statements are true.
17.8 Internet of Things and Dashboards 15
17.5 Q2: Which of the following statements a), b) or c) about Google’s initial
search implementation is false?
a. Google developed a clustering system, tying together vast numbers of inexpen-
sive “commodity computers”—called nodes.
b. Because having more computers and more connections between them meant
greater chance of hardware failures, Google also built in high levels of redundancy
to ensure that the system would continue functioning even if nodes within clus-
ters failed.
c. The data was distributed across all the inexpensive “commodity computers.”
To satisfy a search request, all the computers in the cluster searched in parallel
the portion of the web they stored locally. Then the results of those searches were
gathered up and reported back to the user.
d. All of the above statements are true.
17.5 Q3: Which of the following statements is false?
a. To develop its initial search implementation, Google needed to develop the
clustering hardware and software, including distributed storage.
b. Google published its designs in the research paper “The Google File System,”
but did not open source its software.
c. Programmers at Yahoo!, working from Google’s designs in the “Google File Sys-
tem” paper, then built their own system.
d. Yahoo! open-sourced their work and the Eclipse Foundation implemented the
system as Hadoop.
17.5 Q4: Which of the following statements is false?
a. Two key Hadoop components are HDFS (Hadoop Distributed File System) for
storing massive amounts of data throughout a cluster, and MapReduce for imple-
menting the tasks that process the data.
b. Hadoop MapReduce is similar in concept to the functional-style programming,
just on a massively parallel scale.
c. A MapReduce task performs two steps—mapping and reduction.
d. The mapping step processes the original data across the entire cluster and
maps it into tuples of key–value pairs. The reduction step, which also may include
filtering, then combines those tuples to produce the results of the MapReduce
task.